
Your Shopify dashboard can look healthy while repeat revenue slips. Acquisition still comes in, email sends still go out, and the month closes without a fire drill, but the store has already started leaking value because nobody is spotting which customers are about to go quiet, which ones are worth saving, and which ones should be left alone. That's the job of predictive analytics customer retention, turning scattered behavior into a practical retention system instead of waiting for a quarterly report to tell you what went wrong.
The brands that win here don't treat churn scoring as a curiosity. They use it to decide who gets a reminder, who gets education, who gets a VIP treatment, and who should never receive a discount at all. That's where retention becomes operational, not theoretical, and why a good system compounds across email, SMS, paid retargeting, and loyalty offers, especially when you're working with tools like customizable rewards for retailers that can match incentives to customer behavior without flattening your margins.
Why Most Ecommerce Brands Lose Repeat Buyers Without Realizing It
A lot of DTC teams are watching the right dashboard and still missing the signal that matters. Orders keep coming in, CAC may look acceptable, and the founder still sees new customers every week, yet repeat purchase rate stalls because the team reacts after the lapse instead of before it. By the time a win-back email lands, the relationship has already cooled.
That is why predictive analytics customer retention matters. It turns past activity into a forward-looking signal, so marketing can act on likelihood, timing, and customer value before a buyer drifts out of the repurchase cycle. A practical retention system behaves more like lifecycle operations than a black-box score, because the score only matters when it changes what happens next.
What gets missed without forward-looking signals
Most stores can explain churn after it happens. Fewer can tell you which customers are entering a risky gap, which ones are naturally slow buyers, and which ones are at risk of leaving. That distinction matters because retention problems often stay hidden until the quarter is already gone, and then the team starts debating discounts instead of fixing the trigger logic.
Practical rule: if a customer's behavior changes before their order cadence breaks, the model should react before the repurchase window closes.
The business case is straightforward. Predictive retention can surface customers early enough to intervene, and a published benchmark reports retention rising from 65% to 85%, churn falling from 35% to 15%, and customer satisfaction increasing from 70% to 88% after analytics was applied, which shows why lifecycle action beats reactive cleanup (academic chapter). Another evidence base says customers spend 31% more with companies that retain them successfully, so small gains in repeat behavior can compound quickly across email, SMS, and retention media (industry synthesis).
If you are building retention programs for a DTC brand, a simple loyalty layer can help the model's output turn into something customers feel, not just something analysts monitor. For a practical reference on how reward structures can be adapted to retail behavior, customizable rewards for retailers is a useful example.
Set Retention Goals and Assemble the Right Data Foundation
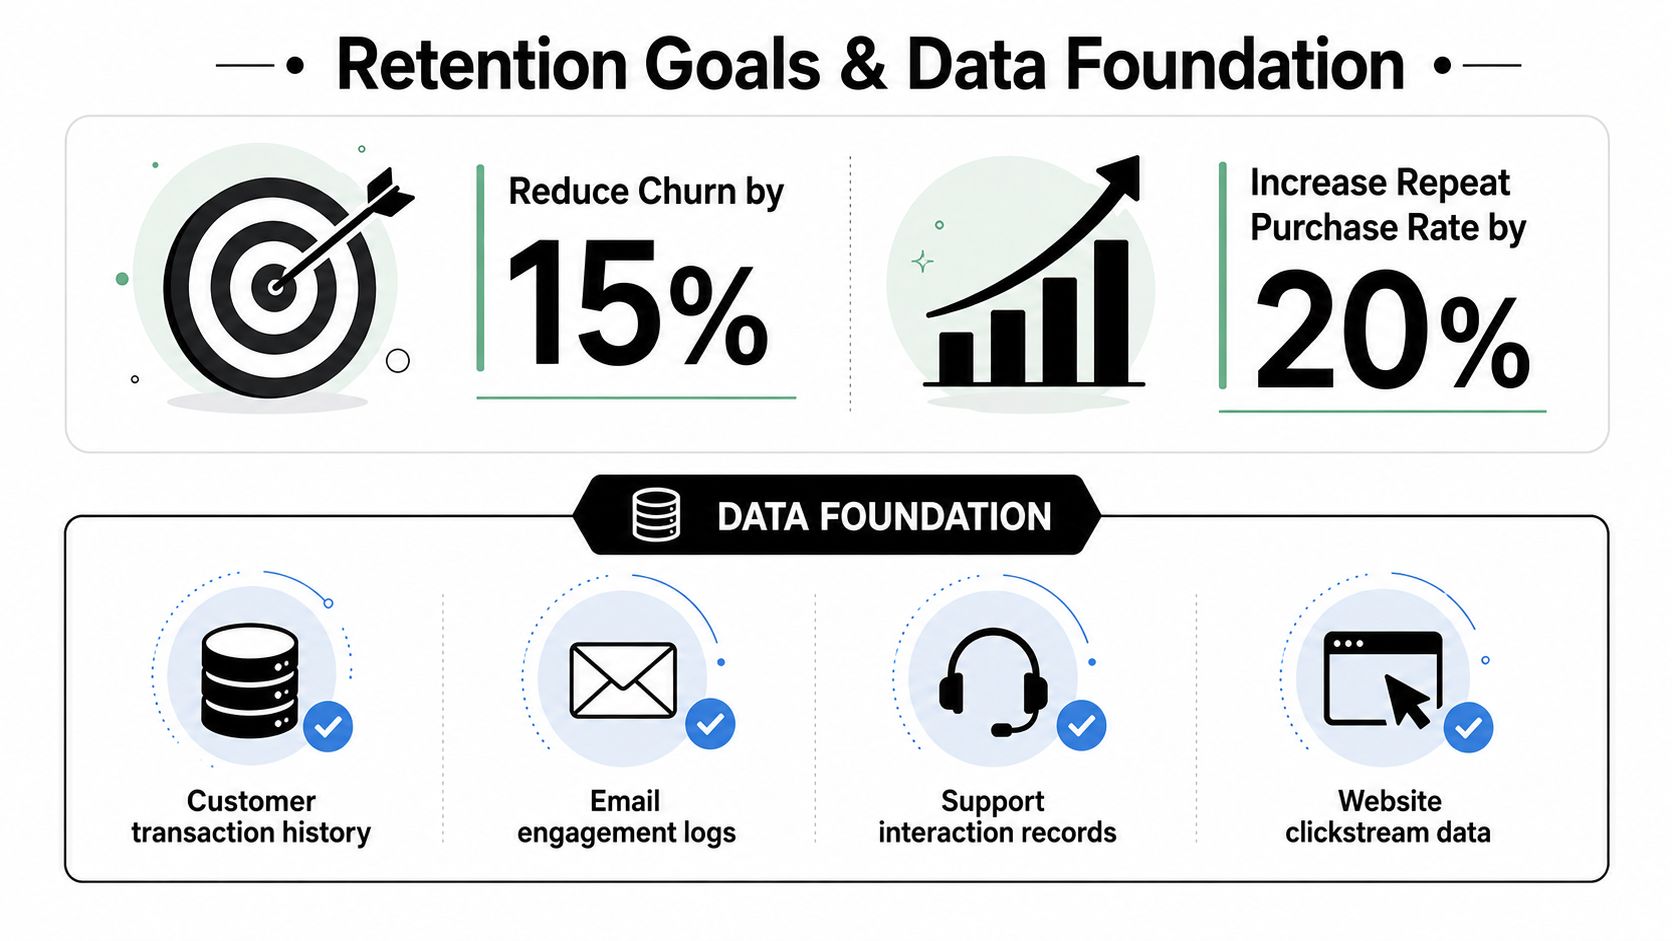
A retention model is only useful if the business goal is clear enough to act on. “Reduce churn” sounds neat, but it leaves the team guessing unless it is tied to a concrete outcome such as repeat purchase rate, customer lifetime value, or retention inside a specific repurchase window. If the goal is vague, the model will optimize the wrong behavior and the marketing team will end up with a score that nobody trusts.
Define the goal in business terms
A retention objective should point to a decision, not a vanity metric. If the brand sells replenishable products, the main goal may be preventing lapsed reorder behavior. If the catalog is broader, the goal may be pushing second purchases or raising lifetime value through higher-frequency cross-sell. The supporting KPIs then fall into place, such as churn rate, repeat purchase rate, service resolution quality, or movement in CLV.
That framing also keeps teams from overrating model accuracy on its own. A model that looks impressive in a notebook but does not move revenue is just an expensive spreadsheet. The question is whether it can identify the right customers early enough for the right intervention.
Pull the data that predicts behavior
A usable retention foundation usually combines transaction history, browse and cart events, email engagement, service tickets, review activity, and loyalty tier movement. An academic chapter notes that teams can use historical, behavioral, transactional, service, and loyalty data together to estimate outcomes such as churn, repeat purchase, renewal, complaint escalation, loyalty-tier progression, cross-sell acceptance, and customer lifetime value (academic chapter). That is the single customer view you need before any meaningful score can exist.
The practical workflow starts by merging data from the ecommerce platform, ESP, helpdesk, and loyalty stack into one customer profile. If those systems disagree on who the customer is, the model will misread normal buying gaps as churn. For a useful example of how reward structures can be adapted to retail behavior, consider how tiered incentives respond to purchasing patterns before they stagnate.
A good readiness check looks like this:
- Identity resolution: confirm the same customer can be matched across store, email, and service systems.
- Behavioral coverage: verify that browse, cart, and email events are captured consistently.
- Transaction depth: make sure order history is long enough to reflect true buying rhythm.
- Service visibility: include ticket themes, complaint frequency, and resolution outcomes.
- Loyalty signal quality: track tier movement, points behavior, and reward redemption.
For a deeper look at first-party collection strategy, the internal guide on first-party data strategy is worth reviewing before anyone touches the modeling layer.
Choose the Right Models for Churn, CLV, and Repeat Purchase
Most retention guides collapse everything into one generic churn score. That's a mistake. A good ecommerce program uses different models for different decisions, because who might leave, who is worth saving, who is likely to buy again, and when they might buy are not the same question.
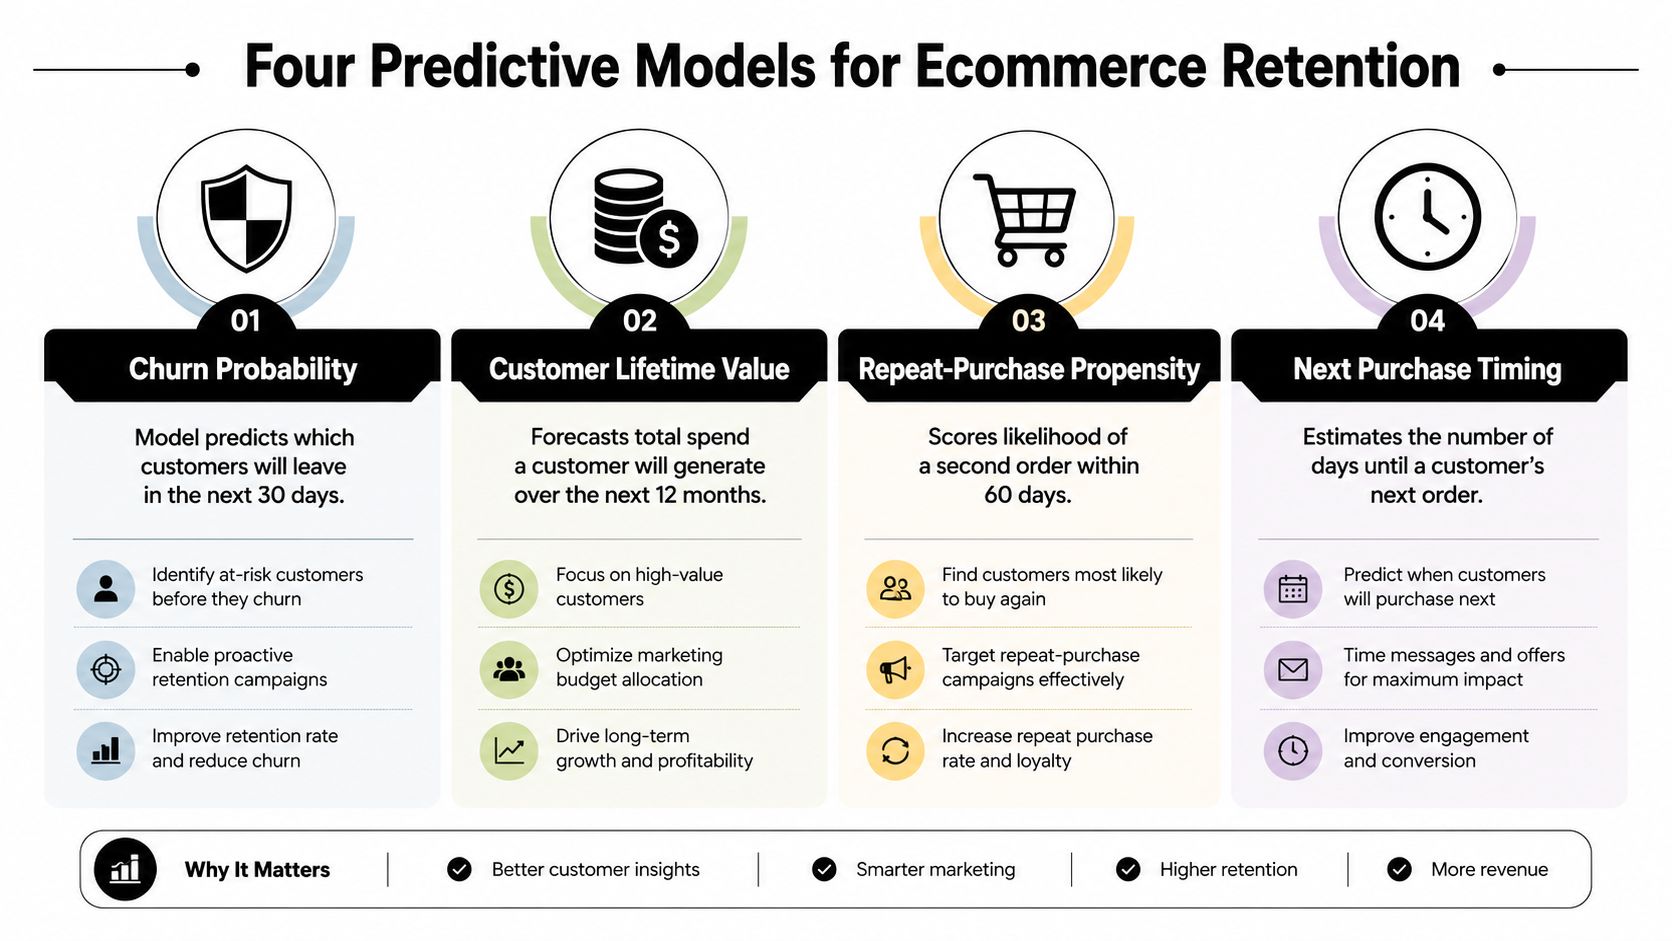
A useful starting point is the lifecycle lens. Churn probability tells you which customers are slipping away. CLV tells you which of those customers deserve the most attention. Repeat-purchase propensity tells you who's likely to convert again. Next purchase timing tells you when to show up. Those outputs work together, not against each other.
Four models, four jobs
A churn model usually works best when it predicts a risk window, not a vague future state. Logistic regression is a strong baseline when the team wants interpretability, while gradient boosting can capture nonlinear patterns in engagement and purchase behavior. For a subscription coffee brand, the output becomes a score that flags which customers are drifting before their next bag should ship. For a beauty brand, it can identify which first-time buyers are getting cold after a product trial.
CLV modeling answers a different question, which is how much the customer is likely to spend over time. That matters because a customer with a moderate churn score may still be a higher-priority save than a low-value account with a worse score. If you want a practical reference for the finance side of that analysis, the guide on boost customer value in 2026 is a useful companion to this model choice.
Repeat-purchase propensity predicts the chance of another order in a defined window. This is often the most actionable model for DTC teams because it drives post-purchase flows, replenishment reminders, and offer suppression decisions. Next-best-offer propensity goes one step further and helps decide which product or incentive fits the customer's likely next move. That's the model that stops teams from blasting random discounts to people who were already going to reorder.
Practical rule: don't use one score to do four jobs. Use four scores to make one retention decision.
| Retention Models Compared for Ecommerce Use Cases | Predicts | Best for | Marketing output |
|---|---|---|---|
| Churn probability | Likelihood of lapse | Early intervention | Win-back and save flows |
| Customer lifetime value | Future value | Budget prioritization | VIP, loyalty, and offer depth |
| Repeat-purchase propensity | Likelihood of another order | Post-purchase lifecycle | Reminder and replenishment flows |
| Next purchase timing | Likely timing of the next order | Send-time and cadence control | Timing-based email and SMS |
For teams that want the mechanics behind CLV calculation, the internal walkthrough on customer lifetime value calculator fits neatly with this model stack.
Build, Validate, and Deploy the Retention Model
The model itself isn't the hard part. The hard part is getting the pipeline clean enough that the output deserves to be trusted by marketing. That starts with extraction, then cleaning missing values and outliers, then feature engineering around recency, frequency, monetary value, session behavior, and engagement decay.
Train on history, not wishful thinking
A sound workflow usually looks like this. Pull historical labels for churn or repeat purchase, transform the raw data into usable features, then train and validate on past behavior before anyone deploys a live score. The point is to test whether the model would have made useful decisions at the time, not whether it can memorize old records.
Technical teams often overcomplicate this stage by chasing exotic algorithms before they've solved the basics. Missing values, duplicate customers, and inconsistent timestamps will do more damage than the choice between two strong model families. A simple logistic regression that's cleanly wired into operations beats a complex model nobody can deploy.
Evaluate in business language
Model quality should be read alongside business lift. A useful framework tracks baseline churn, CLV, model lift, precision, and recall, and one industry guide notes that a lift of 2.0 means the model is twice as effective as random selection at identifying churners (industry framework). That matters because marketers don't buy lift curves, they buy better targeting.
Sparse data is a real issue for new customers and brand-new accounts that haven't purchased yet. In those cases, the model should lean more on early behavioral signals, onboarding engagement, and browsing patterns than on purchase history alone. If you force the system to wait for too much data, you'll miss the exact window where intervention is most valuable.
Deploy with version control and channel fit
Scoring can happen in batches for email and SMS, or in real time at the session level for onsite personalization. Batch is usually the easier first step because the ESP can consume the risk tiers directly. Real-time scoring makes sense when the brand needs to adapt offers, content, or urgency while the shopper is still active.
A safe deployment plan keeps model versions distinct, logs which scores drove which campaign, and preserves the ability to roll back quickly if signal quality drops. That versioning discipline is what stops a working model from becoming an operational liability.
Connect Predictions to Email and SMS Lifecycle Flows
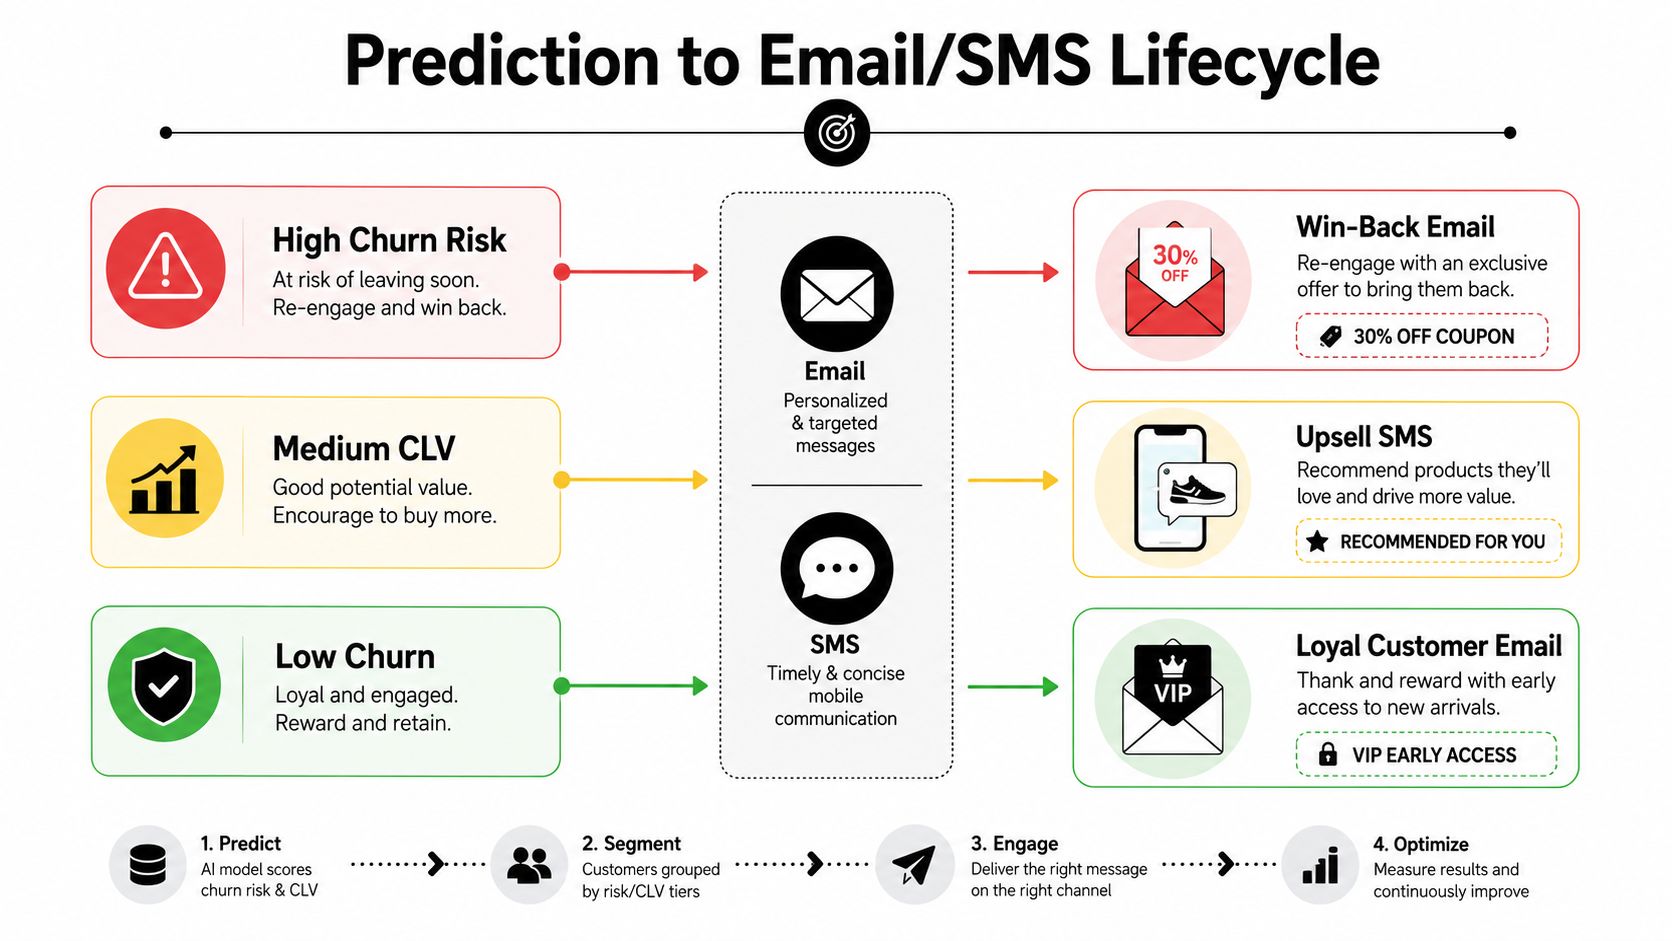
A score on its own doesn't save revenue. The money shows up when the score changes the journey, the message, and the offer. That means the retention team needs a tiered playbook, not one giant discount flow sent to everyone with a pulse.
Match the intervention to the risk tier
High-risk customers should get the most direct save paths, but that doesn't mean the biggest discount by default. If the customer is high value, a value-driven offer, a product education message, or a concierge-style outreach is often a better first move than an aggressive markdown. The model's job is to prioritize the intervention, not to justify a blanket coupon.
Mid-risk customers usually respond better to relevance than urgency. For them, education, social proof, usage tips, and complementary-product recommendations often work better than a hard win-back push. Low-risk customers should be protected from overmessaging, because unnecessary pressure can train loyal buyers to wait for offers.
An industry guidance source makes the same point in another way, noting that effective implementations use different intervention strategies by risk tier instead of one-size-fits-all messaging, and that retention should learn from intervention outcomes as well as churn labels (predictive retention guidance). That's the difference between a smart lifecycle program and a noisy automation stack.
Build two concrete flow maps
A post-purchase flow for a repeat-purchase DTC brand can branch by risk and value. A high-risk, high-value customer gets a fast check-in with a product usage message and a custom incentive only if engagement stalls. A mid-risk buyer gets a reorder reminder, customer reviews, and a category education email. A low-risk buyer gets nothing unless their behavior changes.
A subscription consumables brand should think in renewal windows. The logic is similar, but the creative is different. One branch can send replenishment reminders, another can address delivery friction or billing uncertainty, and the highest-value subscribers can get early access to new bundles or loyalty-tier benefits.
Don't spend discount budget on customers who were already likely to come back. Save the offer for the segment that actually needs it.
For teams building the automation side, the internal guide on email automation workflows is a practical companion to this tiered approach.
The strongest setups also include suppression rules. If a customer just converted, suppress the win-back. If the model says they're low risk, suppress the offer. If the customer is high CLV, route them to the highest-quality treatment your brand can support, not the cheapest incentive you can send.
Measure Retention Lift and Run Closed-Loop Testing
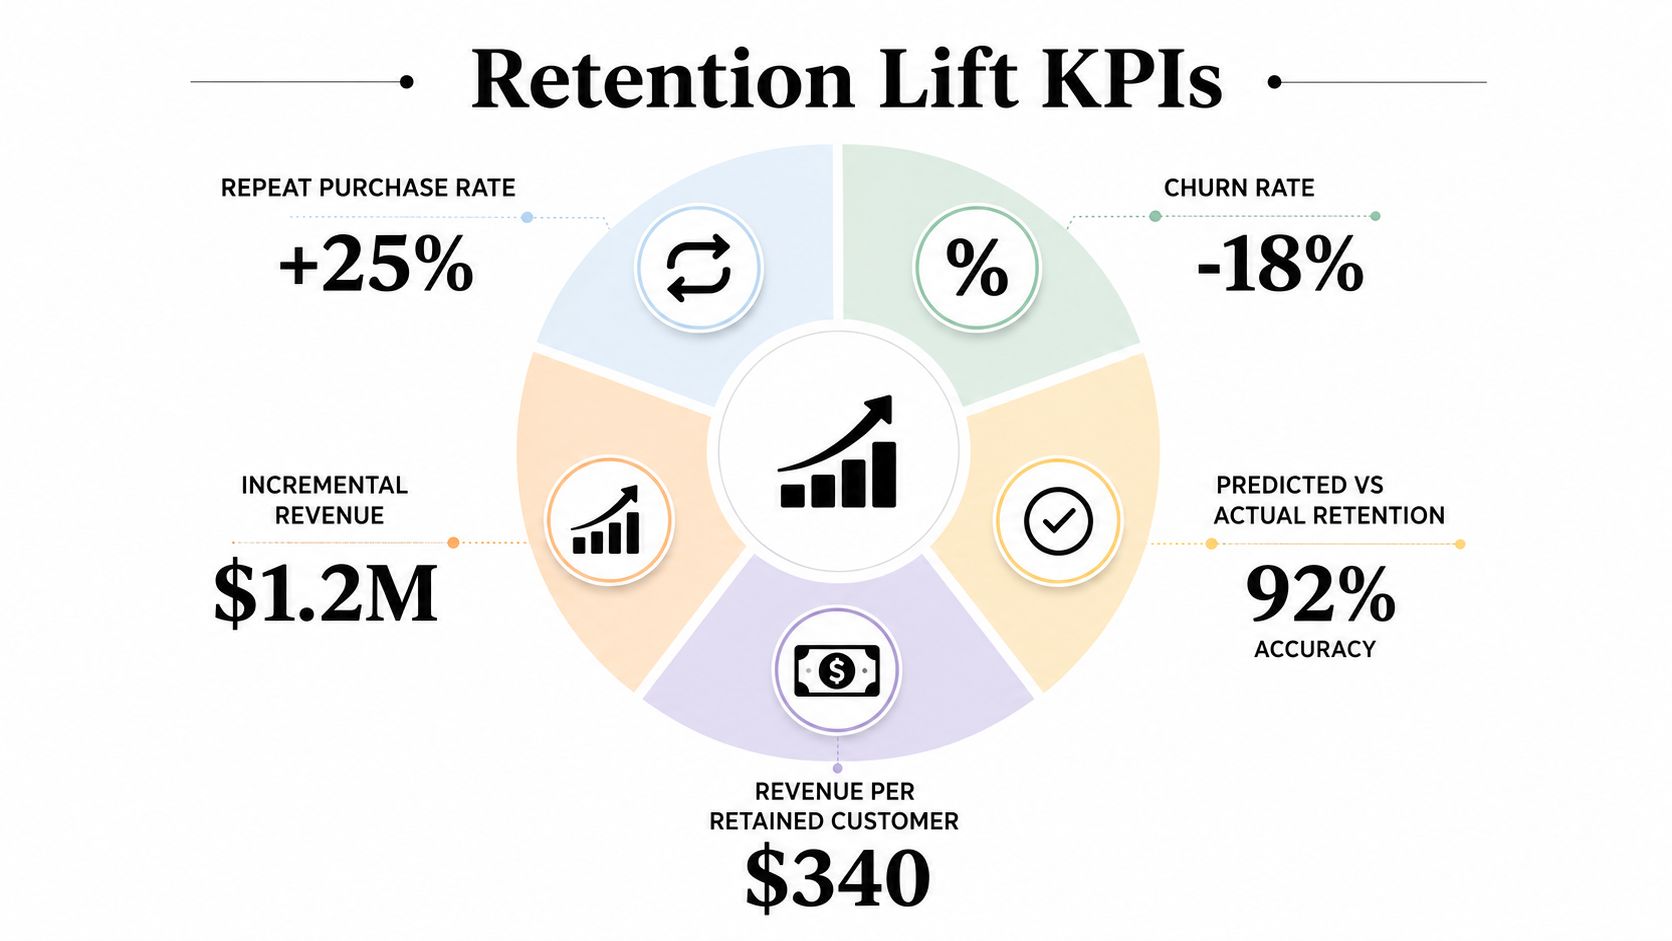
Predictions without measurement are just educated guesses. To know whether the retention program is working, the team has to track repeat purchase rate, churn rate, predicted versus actual retention, revenue per retained customer, and incremental revenue versus a control group.
Build holdouts before you optimize the creative
A holdout group gives you the truth. Without it, every lift claim is contaminated by seasonality, acquisition quality, and normal repeat behavior. Keep a portion of at-risk customers unexposed so you can compare what would have happened without the intervention.
That structure also lets the team test within risk tiers instead of across the whole database. A win-back offer that works for mid-value lapsed buyers may burn margin on high-value repeat purchasers. The best programs test the offer, channel, and cadence separately for each segment.
Feed outcomes back into the model
Closed-loop testing is where the model gets smarter. If a customer saved by a specific intervention stays active, that outcome should inform future scoring and intervention logic. If a discount only shifts timing without changing retention, the system should learn that too.
The practical reporting rhythm is monthly for the marketing team and quarterly for leadership. Marketing needs to see which tier is being contacted, which offer is winning, and where suppression rules are protecting margin. Leadership needs to see whether the retention program is contributing durable revenue or just buying temporary activity.
For a useful framing of how analytics should connect to email performance, the internal resource on analytics email marketing fits naturally with this measurement layer. It's the same principle in a different channel, measure the message, not just the send.
Common Pitfalls and a Practical Starting Plan
The easiest mistake is treating the model as the project. It isn't. The project is the intervention system, and if the score doesn't change what marketing does, the whole thing becomes dashboard theater.
Another common failure is discounting high-CLV customers who never needed saving. That trains buyers to wait for incentives and wastes budget on accounts that would have repurchased anyway. Teams also get burned by ignoring sparse-data early customers, then act surprised when the model underperforms on the very segment that needed it most.
A simple 30-day starting plan
Start with one retention goal, one customer segment, and one flow. Build the data view, score the segment, and launch one tiered intervention with a holdout group. Then review which customers converted, which offers were unnecessary, and which signals should be weighted more heavily.
A solid first-month checklist looks like this:
- Define one goal: pick churn reduction, repeat purchase lift, or CLV improvement.
- Choose one segment: focus on post-purchase buyers, lapsed customers, or subscribers.
- Build one score: start with churn or repeat-purchase propensity.
- Launch one flow: use tiered messaging, not a blanket discount.
- Review one test: compare holdout, offer performance, and margin impact.
If the team can't explain why each customer got a specific message, the program isn't ready to scale. Fix that first, then expand the model stack.
If you want a retention program that moves revenue, Ecommerce Boost helps ecommerce brands turn lifecycle data into smarter email and SMS flows, tighter segmentation, and clearer reporting. Visit Ecommerce Boost to see how a predictive retention system can turn more of your existing customers into repeat buyers.


