
The founder is sending six campaigns a week. Klaviyo reports respectable open rates, the creative is polished, and the list is growing. Yet revenue from email has flattened, while the team keeps debating whether Tuesday morning or Thursday afternoon is the “best” send time.
That debate usually starts in the wrong place. Send time optimization, or STO, isn't a universal clock setting. It's a personalization system that uses each subscriber's historical engagement patterns to choose a delivery window. For a DTC brand, the useful question isn't whether more people opened. It's whether the right people clicked, purchased, stayed subscribed, and bought again.
Why Timing Is the Quiet Lever in Your Email Program
A campaign goes out at the same hour for everyone. One customer checks email before work, another during lunch, and another after the household settles down. The shared delivery time compresses those routines into one average, so a campaign can look healthy overall while missing the moments when individual subscribers are most likely to act.
That makes generic “best time to send email” lists a limited starting point for ecommerce. They rarely account for your customers' behavior, lifecycle stage, local time, or relationship with the product. A best time to send email framework can establish a baseline, but your own revenue data should decide whether that baseline survives.
STO is a system, not a magic hour
STO gathers engagement events, identifies timing patterns for each recipient or cohort, and schedules delivery inside a predicted peak window. The IKEA and Lund University study described STO as a way to match delivery with customer behavior instead of forcing every subscriber into one batch time (IKEA and Lund University study).
A fact sheet reported a 22.82% average open rate for STO emails versus 11.26% for standard emails from January through November 2021 (study reference). That result demonstrates the potential of timing data at scale, not a forecast for every DTC program. Open-rate gains can also reflect differences in audience, deliverability, offer, and measurement.
A 2026 industry review places typical STO open-rate improvement at 5% to 15% relative lift, with click-rate improvement usually around 3% to 10% relative lift (2026 STO review). With a 20% baseline open rate, that range means roughly 21% to 23%, not 30%. Clicks usually move less because the offer, creative, landing page, and purchase intent carry more weight after the message is seen.
Practical rule: Treat STO as an incremental conversion opportunity. If you cannot measure what happens after the open, do not add the operational complexity yet.
The scoreboard comes before the model
Set the measurement rules before activation:
- What data will the model use? Engagement history, click behavior, local time, segment membership, and delivery records need consistent definitions and usable timestamps.
- What stays constant during testing? Hold subject line, offer, creative, audience, landing page, and send frequency steady where possible.
- What proves value? Rank revenue per recipient, conversion rate, repeat purchase, complaints, and unsubscribes above opens.
The investment is defensible only when the timing effect reaches beyond the inbox. STO can earn a permanent place in the program when it improves commercial outcomes without creating unacceptable engagement or retention costs.
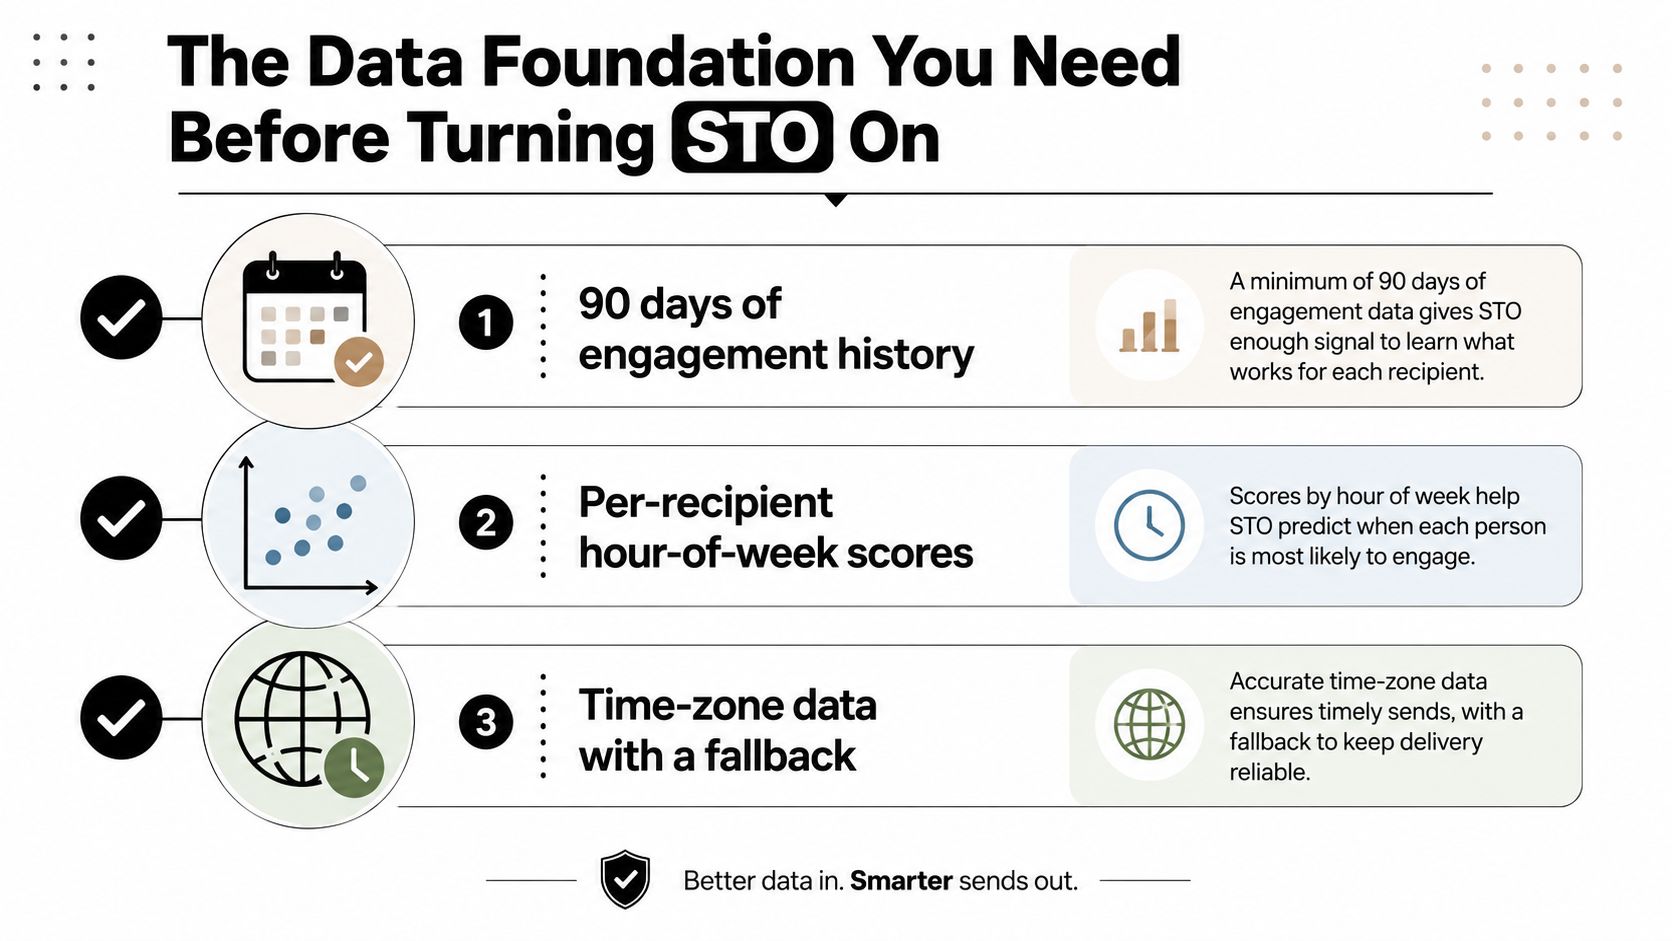
The Data Foundation You Need Before Turning STO On
Before STO chooses a send hour, verify that the behavioral trail can support the decision. Sparse engagement, incorrect time zones, and inconsistent event definitions can produce precise-looking recommendations with little commercial value.
Start with a usable lookback window
Several commercial implementations use 90 days of engagement data to establish timing patterns. Einstein Send Time Optimization in Marketing Cloud Engagement scores all 168 hours in a week for each contact and weighs roughly 20 factors, including sends, opens, and the day of week when a message was opened (Einstein STO details).
That hourly view is more useful than a generic “morning” label. It can separate a Monday-morning pattern from a Sunday-evening pattern, then revise the score as new events arrive.
Use a readiness checklist that covers:
- Engagement history: Record delivery, open, click, conversion, unsubscribe, and complaint events with timestamps.
- Recipient-level timing: Keep hour-of-week behavior for each contact instead of reducing the audience to one average.
- Time-zone data: Send in local time where known, and assign unknown contacts to a defined fallback group.
- Event separation: Analyze open and click timestamps independently. Clicks generally indicate stronger intent than opens.
- Lookback discipline: Apply the same meaningful review period instead of changing the window after each campaign.
If the audience layer is still being organized, audience segmentation with Sendvo can help structure recipients before timing predictions are applied.
Treat benchmarks as context, not forecasts
A historical 22.82% versus 11.26% open-rate comparison shows that STO produced a measurable result in one large-scale setting. It does not establish the outcome for your program. Use a modest planning assumption and validate it against revenue, conversion, and retention costs rather than treating an open-rate comparison as a promise. Your model needs enough consistent behavior to separate a repeatable timing pattern from noise.
STO is ready when the data is timestamped, contact-level, and commercially measurable. If those conditions are missing, fix the tracking foundation before adding model-driven send-time complexity.
Segmentation Strategies That Make Timing Actually Different
A global best hour is usually a compromise. It may be acceptable for a small broadcast, but it hides the fact that a prospect, a repeat customer, and a lapsed buyer have different reasons to open.
Start by separating lifecycle stage, channel behavior, and timezone. A prospect may need a daytime education message, while a repeat customer may respond better to an evening replenishment reminder. A lapsed buyer may require a carefully timed win-back, but the model should not treat old engagement as equally reliable to recent behavior.
One benchmark covering 4.2 million emails identified an ecommerce peak around 8 PM, while broader analyses continue to favor weekday mornings in the recipient's local time (2026 send-time benchmark). Those findings aren't contradictory. They suggest that the right window depends on audience composition, email type, geography, and objective.
Build cohorts around intent
Use the following defaults as starting hypotheses, not permanent rules:
| Segment | Default Window | Notes |
|---|---|---|
| Prospect | Weekday morning in local time | Test educational content against a daytime control |
| First purchase | Local-time window based on recent engagement | Prioritize onboarding and product-use guidance |
| Repeat customer | Evening challenger window | Useful for replenishment and lifestyle-led offers |
| Lapsed customer | Stable control plus a reactivation challenger | Don't assume old behavior still predicts current attention |
| Unknown timezone | Fixed fallback window | Keep this group separate so it doesn't contaminate local-time results |
Klaviyo or another ESP can support these cohorts using lifecycle fields, purchase history, engagement recency, and geography. Keep the “unknown timezone” group visible. Assigning those subscribers to the sender's timezone creates a false local-time test and can send messages at unnatural hours.
The same logic applies to creative. Timing can't rescue an irrelevant message, so subject-line planning still matters. Teams working on property or location-led campaigns can use proven subject lines for realtors as a reminder that the message angle and the delivery window have to work together.
For a deeper operating model, review these customer segmentation strategies and map each segment to a distinct business objective before assigning timing rules.
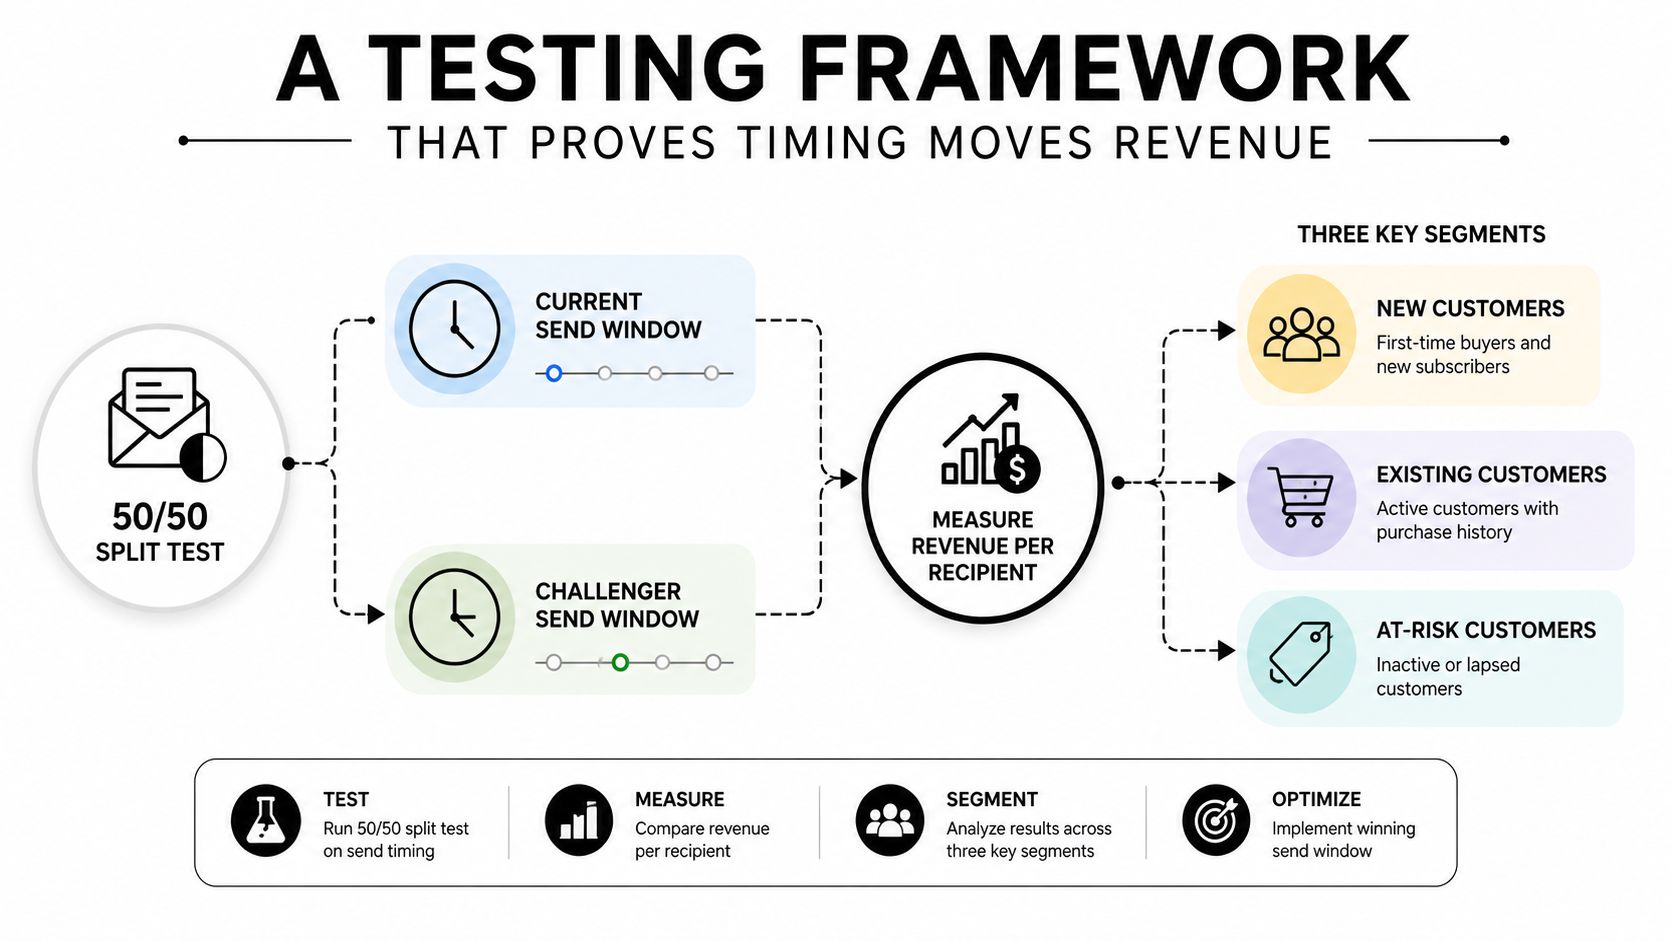
A Testing Framework That Proves Timing Moves Revenue
A send-time test earns its place only when a timing change improves revenue beyond the inbox. Hold the audience, subject line, offer, creative, landing page, and campaign type steady. Change the delivery window, then track whether additional attention becomes additional buying.
Choose between a challenger test and a holdout
Use a 50/50 split when the question is whether one challenger window beats the current schedule. Send the same content type across three consecutive sends, and use click-to-open rate as the primary engagement measure, alongside revenue outcomes (Einstein STO testing guide).
A holdout keeps 10% to 20% of each segment on a fixed-time control while the remaining audience receives optimized delivery. This preserves a baseline across recurring lifecycle flows and makes incremental revenue easier to assess.
| Decision | 50/50 challenger test | 10% to 20% holdout |
|---|---|---|
| Best use | Validate one timing hypothesis | Monitor incremental lift continuously |
| Control | Current send window | Fixed-time control |
| Main strength | Simple comparison | Stable baseline across campaigns |
| Main risk | Less efficient test exposure | Smaller control may be noisy |
Start with click-to-open rate and revenue per recipient. Treat opens as a diagnostic, then review conversion rate, complaints, unsubscribes, and repeat behavior. Higher clicks without higher revenue indicate that the new window is capturing attention without improving buying intent.
Keep the experiment honest
Randomize within each lifecycle segment and timezone group. Assigning every VIP customer to the challenger while prospects remain in control confounds timing with audience quality.
Document the test before launch:
- Lock the content: Keep the subject line, offer, body, and destination unchanged.
- Define the window: Record the current and challenger schedules in recipient-local time.
- Set the observation period: Allow enough time for clicks, conversions, complaints, and unsubscribes to register.
- Use a recovery rule: If results stall, pause expansion, inspect data quality and deliverability, and restore the stable schedule for the affected campaign.
A single send cannot prove commercial value. The challenger wins when its timing produces useful revenue improvement without unacceptable customer or delivery costs. Use this A/B testing approach for email campaigns to record variables, controls, and decision rules before launch.
A DTC Case Study in Time-Sensitive Lifecycle Sends
Consider a representative beauty-brand launch with a founder drop. The team wants VIP customers to see the product when their day begins, while non-openers need a second opportunity that doesn't collide with the first send.
The test has two arms. The challenger group receives the launch email at 9 AM Tuesday in each VIP recipient's local time, then a 7 PM cart reminder goes to eligible non-openers. The control group receives the same messages at the brand's old 10 AM batch time. The content, offer, audience definitions, and suppression rules stay unchanged.
Set up the dashboard before launch
The team tracks:
- Open rate: A directional visibility signal.
- Click-to-open rate: The primary measure of whether opened emails create interest.
- Conversion rate: The first downstream action.
- Revenue per recipient: The commercial comparison across groups.
- Unsubscribe rate: A direct cost of poor timing or excessive pressure.
- Complaint rate: A deliverability and customer-experience warning.
After 72 hours, the team compares the challenger and control within the same lifecycle and geography cohorts. It doesn't declare a winner from VIP performance alone. It checks whether the evening reminder generated incremental purchases, whether the local-time launch increased clicks, and whether any engagement gain came with more unsubscribes or complaints.
This structure also fits broader Types of Email Automation Flows, especially when launch emails, cart recovery, and post-purchase messages need separate timing logic. If the result is positive, the team can promote the timing rule into the flow while retaining a small control group for future monitoring.
The important point is what the case study refuses to claim. Without verified revenue and cohort results, nobody should invent a lift. The blueprint is useful because it tells the team exactly what to measure before making that claim.
KPIs, Pitfalls, and When to Walk Away
The beauty brand's first launch test exposes STO's operational cost. Local-time delivery can spread sends across the day, while incomplete timezone data or missing business-hour limits can produce small spikes at inconvenient hours. Timing earns its complexity only when commercial gains outweigh these delivery risks.
Use a business scoreboard
Open rate belongs in the diagnostic column, not the decision column. Track:
- Revenue per recipient: Did timing create more value per delivered email?
- Conversion rate: Did more recipients complete the intended action?
- Repeat-purchase delta: Did the effect continue beyond the campaign?
- Complaint rate: Did recipients find the schedule intrusive?
- Unsubscribe rate: Did list retention deteriorate?
- Click-to-open rate: Did timing improve the quality of attention?
Review these measures together. A higher click-to-open rate is useful only if it supports conversions, revenue, or repeat purchases. Use the email campaign performance metrics guide to keep reporting tied to commercial and retention outcomes rather than surface-level attention.
STO can also create inbox-placement swings when many contacts receive messages within narrow windows. Validate timezones, set business-hour guardrails, and define a fallback schedule before activation. If the model cannot control delivery concentration, its incremental revenue may not justify the added operational risk.
Know the failure patterns
Three mistakes appear repeatedly:
- Testing a small or unstable list: Sparse behavior produces unreliable predictions and can make a minor difference look meaningful.
- Ignoring complaints: An open-rate lift does not justify more complaints or unsubscribes.
- Chasing opens: Visibility is not revenue, especially when clicks depend on the offer and creative.
Walk away from STO for a campaign when the send is operationally urgent, the audience has too little history, or the timing window could confuse customers. A fixed schedule is often more responsible for a short-lived promotion, a transactional message with a known service expectation, or any campaign whose model cannot respect local time.
The final test is simple: compare the optimized schedule with a control on revenue, conversion, retention, and recipient harm. If the gain exists only in opens, keep the simpler schedule.
Your 90-Day Send Time Optimization Rollout Plan
STO should earn its complexity in stages. Assign one owner to data quality, one to ESP configuration, one to experimentation, and one to commercial reporting. Agree before launch on the conditions for continuing, iterating, or pausing. Timing matters only if its effect survives the inbox and improves commercial outcomes.
Days 1 through 30 involve readiness
Audit the last 90 days of delivery, open, click, conversion, complaint, and unsubscribe events. Validate recipient time zones, identify unknowns, map lifecycle segments, and confirm that the ESP can use historical engagement without changing campaign content. Check whether reporting can connect each send to revenue and conversion.
At day 30, activate only when timestamps are trustworthy, fallback behavior is defined, and the reporting owner can tie engagement to commercial results. If any condition fails, repair the data instead of activating a model.
Days 31 through 60 belong to one flow
Choose one recurring lifecycle flow, usually cart abandonment, and compare optimized delivery with a fixed control. Keep a 10% to 20% holdout as a stable reference while the remaining segment receives the challenger schedule, following established holdout guidance.
At day 60, continue when revenue per recipient and conversion rate improve without an unacceptable rise in complaints or unsubscribes. Iterate when clicks improve but revenue remains flat. Pause when delivery problems appear or the control consistently wins. Open-rate lift alone does not justify added operating work.
Days 61 through 90 test expansion
Apply the proven rule to selected launch campaigns, then coordinate timing with SMS to prevent overlapping pressure. Retain segment-specific controls where possible, especially for VIPs, repeat buyers, lapsed customers, and recipients with unknown time zones.
At day 90, ask: Does STO produce enough downstream value to justify the operational overhead? Compare revenue, conversion, retention, complaints, and unsubscribes against the control. If the answer is no, keep the clean data foundation and return to local-time or segment-based scheduling. If yes, expand gradually, preserve measurement controls, and review the KPI stack regularly.
Ecommerce Boost helps DTC brands build lifecycle campaigns, segmentation, A/B tests, and reporting systems that connect email timing with conversions, repeat purchases, and customer lifetime value. Visit Ecommerce Boost to discuss whether STO fits your data, audience, and growth goals.


