
The most popular advice about subject line A/B testing is also the least reliable: write a shorter subject line, add personalization, and crown the version with the higher open rate. That approach can produce attractive reports while sending fewer qualified shoppers to your product pages. A subject line test should help you make better commercial decisions, not merely create a larger inbox number.
For ecommerce teams, the practical question is not only which version earns attention. It's which version attracts the right attention, generates clicks, supports purchases, protects list health, and keeps subscribers engaged over time. The framework below treats open rate as one directional signal, then puts downstream performance and segment behavior in charge.
Why Open Rate Is the Wrong North Star
Open rate is useful for diagnosing inbox visibility, but it isn't a complete measure of message quality. Apple Mail Privacy Protection has made opens less reliable, so a subject line that wins on opens can still lose on clicks, conversions, or customer value. This overview of typical email open rates can provide context, but context isn't the same as a testing objective.
Clickbait creates the most obvious failure. A dramatic promise may persuade a subscriber to open, then disappoint them when the email content doesn't match the expectation. That mismatch can produce weak clicks, unsubscribes, spam complaints, and poorer future engagement. In contrast, benefit-led copy may attract fewer casual opens while bringing more shoppers with a clear reason to act.
Consider the difference between a 15% open rate with 3% click-through rate and a 35% open rate with 0.5% click-through rate. The first scenario produces stronger qualified engagement, even though the second looks better in an open-rate report. The comparison doesn't establish revenue by itself, because conversion value depends on the offer, audience, and landing page, but it demonstrates why surface-level winners can mislead.
| Metric | Variant A, Clickbait | Variant B, Benefit-Driven |
|---|---|---|
| Open rate | 35% | 15% |
| Click-through rate | 0.5% | 3% |
| Likely attention quality | Broad but weak intent | Narrower, stronger intent |
| Testing risk | Inflated opens with poor follow-through | Lower opens but better qualification |
| Primary audit | Clicks, complaints, unsubscribes | Revenue, conversion, retention |
Choose the metric before the subject line
For a subject line test, track click-through rate, revenue per recipient, conversion rate, and retention signals alongside opens. Revenue per recipient is especially useful for promotional campaigns because it connects inbox behavior to the commercial result. For non-purchase campaigns, clicks or downstream actions may be the more appropriate primary measure.
A strong test report should answer three questions:
- Did the subject line attract attention?
- Did that attention produce meaningful action?
- Did the variant damage subscriber or deliverability health?
The answer may differ by segment. A win-back audience might respond to a direct reactivation message, while repeat customers may prefer product relevance over manufactured urgency. Generic character-count rules can't capture those differences.
Practical rule: Treat open rate as an inbox diagnostic, not the final definition of success.
Framing a Testable Hypothesis
Random tweaks waste valuable send volume. Before creating two subject lines, define the audience, the single variable, the expected behavior, and the metric that will decide whether the test taught you something.
A useful hypothesis has a clear structure: among a named segment, changing one subject-line element should influence one business outcome. “Let's try emojis” isn't testable enough. “Adding an emoji to a welcome-series subject line will increase qualified clicks among new subscribers” gives the team a variable, an audience, and a downstream question.
Build the experiment in four decisions
Start with the segment. Separate new subscribers, first-time buyers, repeat customers, cart abandoners, and inactive subscribers where the campaign logic allows it. A subject line can perform differently across lifecycle stages because the recipient's motivation differs.
Choose one variable. Possible variables include length, personalization, urgency, benefit framing, question versus statement structure, and emoji use. Keep the sender name, preview text, email content, send time, offer, and landing page unchanged. A practical guide to email campaign A/B testing reinforces the value of isolating the element being tested.
Name the outcome. Use opens as a directional metric for an inbox-envelope test, but validate the result with clicks, replies where relevant, conversion, or revenue. A subject line that creates curiosity but attracts low-intent traffic hasn't necessarily won.
Define the decision window. Decide in advance when you'll assess the result and what evidence would justify applying the learning. This prevents early open spikes from controlling the conclusion.
Use campaign context to shape the comparison
For a flash sale, compare urgency with a concrete benefit, not two unrelated creative ideas. For example, one version might emphasize limited availability while the other explains the shopper's gain. For a product launch, compare a question-based framing with a clear statement, then inspect whether the open-rate difference survives into product-page visits.
New subscribers may respond to clarity and reassurance. Repeat customers may respond better to relevance based on purchase history. Cart abandoners often need a reminder of the product or friction removed from the next step, while inactive subscribers need a message that earns attention without pretending the relationship is stronger than it is.
A good hypothesis also includes a restraint: what you aren't changing. If the subject line, preview text, design, and offer all change together, the result may be interesting, but it won't tell you which decision caused it.
Sample Size and Statistical Significance
A small list can produce a convincing winner by chance. Split the audience into control and treatment groups, keep the email identical apart from the subject line, and define the primary metric before sending. Open rate can provide an early read, but it should not be the final business decision. The historical subject-line testing baseline offers context on why disciplined measurement matters more than choosing the line that earns more opens.
Industry guidance often places subject-line tests at 5,000 to 10,000 emails per variant when the goal is statistical significance. A 20,000-email test, with 10,000 per subject line, can reliably detect a 2 to 3 percentage-point open-rate difference, depending on the baseline and test design. Treat those figures as planning references, not guarantees. The difference you can detect depends on your starting rate, audience consistency, chosen metric, and minimum commercially meaningful lift.
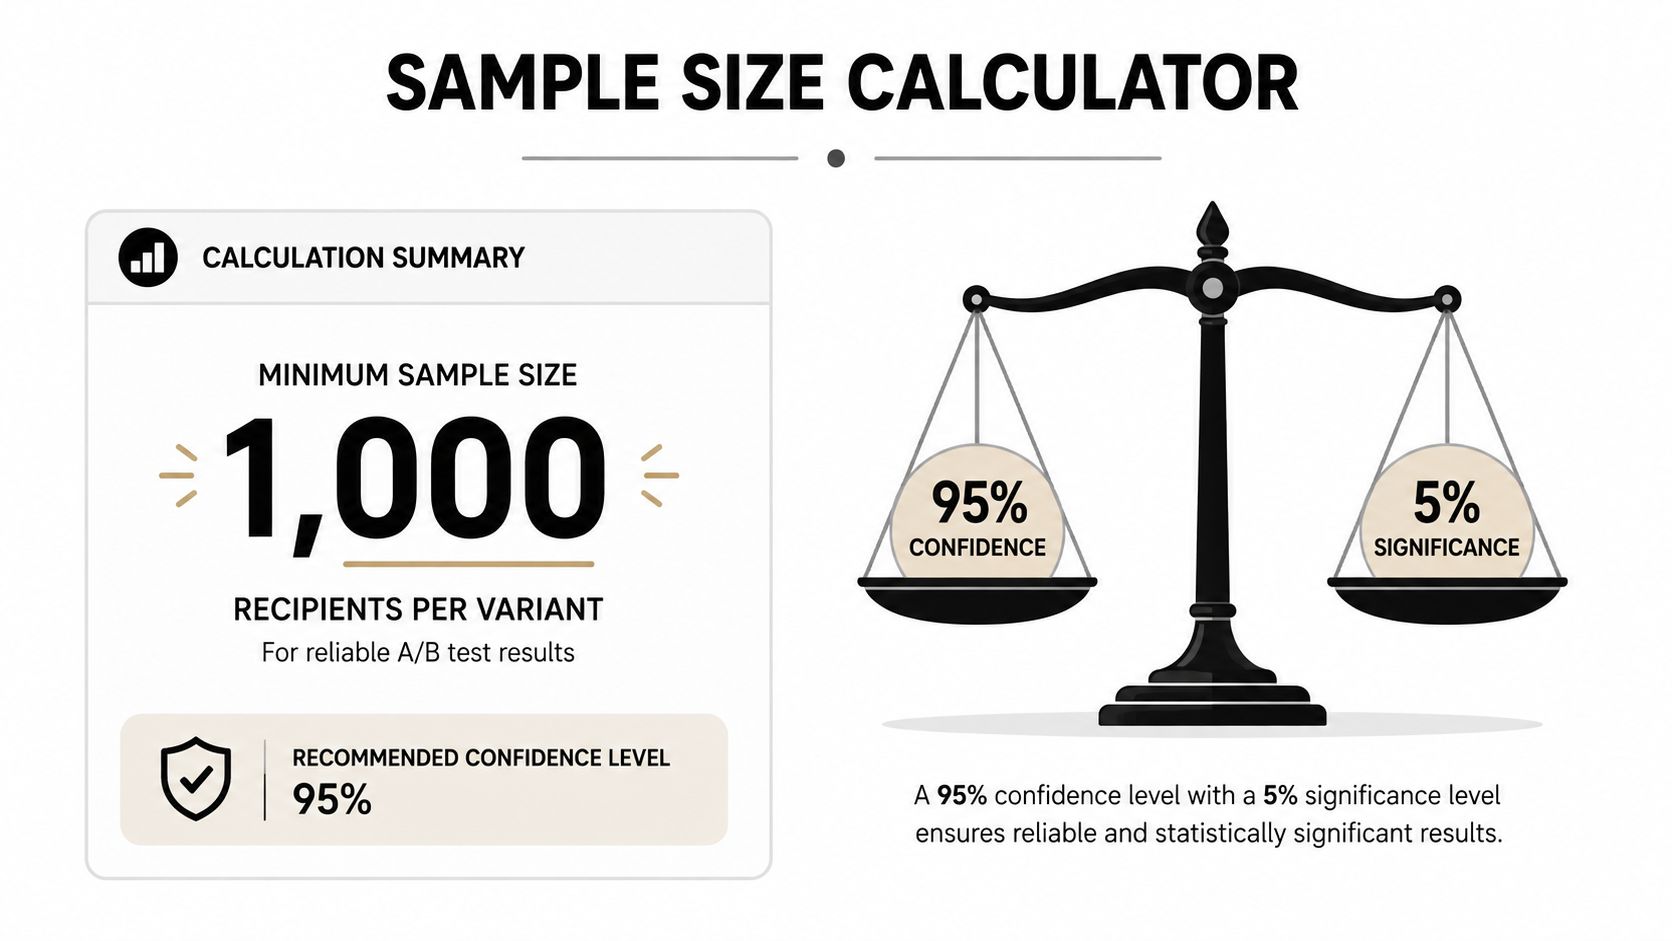
Smaller brands still have useful options. Practitioner guidance commonly uses 500 sends per version as a practical floor, with 1,000 or more per variant preferred when the team needs a steadier read. Below that level, random variation can dominate the result. A minimum of roughly 100 successful events per variant is also cited as a useful condition for identifying a meaningful difference, though event volume alone does not establish significance.
Statistical and practical significance are different
A statistically credible result can have little commercial value. If one line raises opens without increasing clicks, orders, or revenue, adding it to the permanent playbook may reward curiosity rather than customer intent. A promising revenue difference can also remain uncertain when the sample is too small, so record the result as directional instead of forcing a winner.
A 5,000-subscriber list might allow 2,500 recipients per variant, but that allocation may not detect the lift your business considers meaningful. A 25,000-subscriber list gives you more room for a controlled comparison, while a 100,000-subscriber list can support larger samples and cleaner segment analysis. These are allocation examples, not proof of significance. Enter the expected baseline and minimum meaningful difference into a sample-size calculator before launch.
Constant Contact recommends at least 1,000 contacts per subject line for statistical significance and describes an even split as the normal setup. Its subject-line A/B testing guidance provides an operational reference for configuring the comparison inside an ESP.
Fixed samples beat impulsive stopping
Use a fixed sample when the audience size is known and the evaluation window is practical. Sequential testing can work for ongoing experimentation, but the team needs a defined method and stopping rule. Checking results repeatedly until one version moves ahead increases the chance of calling a false winner.
Some independent guidance warns that significance may be difficult below 50,000 people, especially when the test aims to detect subtle differences across broad audiences. Mastercard's email A/B testing guidance underscores how list size affects confidence. With a smaller audience, test a larger behaviorally meaningful change, examine downstream engagement, and document inconclusive results rather than turning noise into a rule.
Running the Test in Your ESP
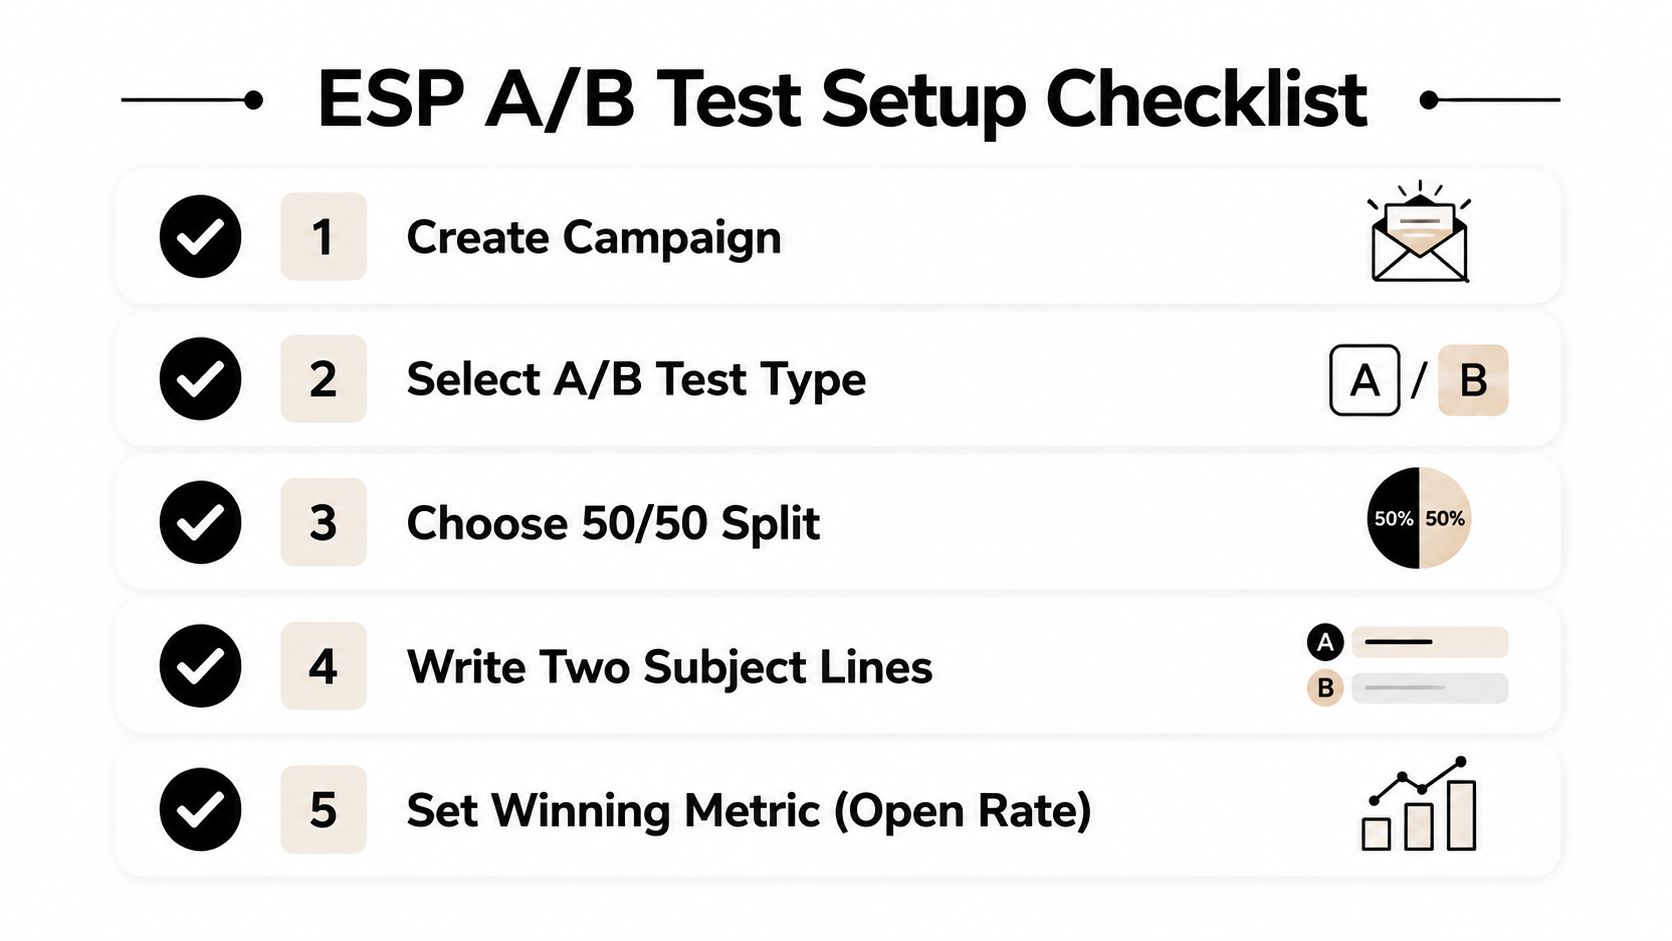
The mechanics vary across Klaviyo, Mailchimp, and HubSpot, but the experimental logic stays the same. Build one campaign, create two subject-line versions, use a randomized 50/50 split where possible, and keep every other campaign input identical. Klaviyo users can work through campaign A/B testing and segment conditions, Mailchimp users can use its subject-line testing workflow, and HubSpot users can configure an A/B email with a defined winning metric.
Configure the audience before the creative
Start with a clean segment. Exclude chronically unengaged subscribers when the purpose is performance learning, because sending aggressive tests to people who rarely interact can create unnecessary deliverability pressure. Separate new customers from returning customers, and suppress anyone already receiving the same message through a flow.
A sample-then-send setup can roll the winning version to the remainder of the audience, but it introduces timing bias. The first group receives the email earlier, and the later group may behave differently because attention decays, inventory changes, or the commercial context shifts. A clean 50/50 broadcast is usually easier to interpret when the campaign isn't time-sensitive.
For teams managing broader lifecycle programs, Klaviyo email marketing services can be relevant when segmentation, flows, and testing need to work together rather than as isolated sends.
Control timing and evaluation
Send both variants at the same time, on the same day, through the same infrastructure. Day-of-week effects, send-time optimization, and audience routines can all influence engagement, so don't test a subject line while changing delivery timing.
A two-hour read window is too short for B2C ecommerce because early engagement doesn't represent the full response curve. For broadcast tests, guidance commonly recommends 24 to 48 hours, with 24 hours suitable for faster-reading lists and up to 48 hours for slower habits. Broadcast testing guidance supports using a complete but practical window. Don't run the test during a major sale event if normal behavior has shifted. A seasonal promotion, launch, or unusual discount can overpower the subject-line variable.
Run a launch checklist
Before sending, verify:
- Merge tags: Confirm names and dynamic fields render correctly in both variants.
- Preview text: Check that the preheader supports the subject line and doesn't create a misleading combined message.
- Tracking: Keep UTM parameters and destination URLs identical across variants.
- Exclusions: Remove flow recipients, recent purchasers, internal addresses, and suppressed contacts where appropriate.
- Winner metric: Confirm the ESP is evaluating the intended metric and time window.
A subject line test is only as clean as its operational setup. Creative discipline can't rescue a contaminated audience or inconsistent send.
Interpreting Results Beyond the Winner
The ESP may announce a winner, but the strategist still has to decide whether the result deserves action. Start by comparing open rate with click-through rate, revenue per recipient, conversion rate, unsubscribes, spam complaints, and any deliverability indicators available in the account. Audit the downstream signals over 7 days so late purchases and delayed opt-outs aren't ignored.
Build an engagement-quality scorecard
A scorecard prevents one inflated metric from dominating the conversation. Assign weights before reviewing the result, not after seeing which version you prefer.
| Metric | Variant A | Variant B | Weight | Notes |
|---|---|---|---|---|
| Open rate | Record result | Record result | Directional | Less reliable because of privacy features |
| Click-through rate | Record result | Record result | High | Measures qualified interest |
| Revenue per recipient | Record result | Record result | Highest for sales sends | Connects the test to commercial value |
| Conversion rate | Record result | Record result | High | Check post-click action |
| Unsubscribe rate | Record result | Record result | Protective | Watch for relevance or trust problems |
| Spam complaints | Record result | Record result | Protective | A negative signal for list health |
| Retention signal | Record result | Record result | Strategic | Consider repeat engagement and future value |
A subject line that wins opens but loses revenue per recipient shouldn't become the default. The same applies to a version that produces more clicks but attracts bargain hunters who never convert. Segment-level reporting matters because an aggregate winner can conceal opposite behavior among new subscribers and loyal buyers.
Urgency is a good example of the trade-off. Recent analysis reports that urgency words can increase unsubscribes by 28%, while questions can improve opens yet reduce clicks by 6%. The 2026 subject-line statistics analysis frames these as competing outcomes, not universal rules. Use the findings as a reason to inspect list health and click quality, not as a reason to ban urgency or questions.
Turn one result into a learning system
Don't rewrite the playbook after one test. Require at least three consecutive tests with consistent directional results before treating a pattern as a dependable strategic rule. Document the hypothesis, segment, campaign type, variants, evaluation window, primary result, secondary effects, and next implication in a shared testing log.
A winning subject line is an observation. A repeatable audience insight requires a pattern.
The log should capture why the team thinks a result occurred. “Benefit framing won” is less useful than “Repeat customers clicked more when the subject line named the product outcome instead of the promotion.” That explanation can guide the next test without pretending one campaign proves a universal rule.
Real Examples and Scaling Learnings
Publicly documented testing can offer useful proof, but the exact brand examples requested here aren't available in the verified data. I won't invent a skincare brand, apparel company, or subscription-box result, sample size, ESP configuration, or subject-line template. The responsible alternative is to use verified evidence and practical templates that a team can adapt and test.
A Smart Insights case study provides a strong real-world benchmark. The treatment subject line produced a 104.5% open uplift for inactive subscribers and a 30.5% uplift for active subscribers. Click uplift reached 228.5% for inactive users and 103.3% for active users, with all metrics exceeding 99% statistical significance. The Smart Insights subject-line testing case study shows that audience alignment can create more than a marginal open-rate change, while also reinforcing the need to distinguish active and inactive behavior.
Use templates as hypotheses, not conclusions
For a skincare welcome flow, test an emoji version against a no-emoji version while keeping the preview text and email content fixed:
- “Your routine starts here ✨”
- “Your routine starts here”
For a win-back flow, test a direct reactivation frame against a benefit-led frame:
- “Still thinking about your next routine?”
- “Build your next routine with products you'll use”
For apparel, compare urgency with customer benefit without assuming either will win:
- “Last chance to shop your size”
- “Find your perfect fit”
For a subscription box, compare shallow personalization with recommendation-based personalization:
- “Your next box is waiting, [First Name]”
- “[First Name], we picked a box for your preferences”
The exact outcome will depend on segment, offer, product, and timing. Teams looking for broader lifecycle ideas can also review these email tips for print on demand sellers when building campaigns around product relevance and repeat purchases.
Scale learnings by campaign family
Build a quarterly calendar around learning categories rather than random creative changes. Give priority to high-volume or high-value campaigns, then rotate through benefit framing, urgency, personalization depth, question versus statement, and emoji use. Keep a separate record for welcome, cart recovery, post-purchase, win-back, and broadcast campaigns, because a result from one lifecycle context shouldn't automatically govern another.
Use example subject lines for emails as an idea source, then turn each concept into a controlled hypothesis. The scaling rule is simple: repeat the promising variable across comparable campaigns, check downstream outcomes, and only promote the learning when the direction holds.
Ecommerce Boost helps online retailers plan lifecycle campaigns, build welcome, browse, cart recovery, post-purchase, and win-back flows, and connect A/B testing to conversions, repeat purchases, and customer lifetime value. Visit Ecommerce Boost to explore its email marketing services and request a consultation focused on turning subject-line testing into measurable ecommerce growth.


