
Last quarter's engagement deck is due, the stakeholder asks for cart recovery performance, and SFMC shows a blank where the numbers should be. That's the moment many teams discover that the dashboard isn't the source of truth, Data Views are. If you know which table to query, what the fields mean, and when the 6-month retention window closes, you can build lifecycle reporting that still works when the UI doesn't.
For ecommerce teams, that matters because the same system tables that hold sends, opens, clicks, bounces, unsubscribes, and complaints also support the decisions behind cart recovery, win-back, and sunsetting. The catch is that the platform only keeps the native engagement history for about 180 days, so anything older needs to be copied into custom storage before it disappears from queryable view 6-month Data View retention behavior. If you're mapping this work into a broader data strategy, first-party data strategy in ecommerce gives the right context.
SFMC data view fluency separates a team that guesses from a team that segments precisely. The rest of this reference stays at table level, because that's where the actual work happens.
Why SFMC Data Views Matter for Ecommerce Teams
The failure mode is usually simple. A marketer asks for last quarter's engagement by cohort, the query window is empty, and the team realizes the report was built on native history that has already aged out. That is exactly where SFMC Data Views become operational, because they are the read-only SQL layer underneath send and engagement reporting, not just another admin feature.
These tables are the place to pull event-level records for opens, clicks, bounces, complaints, and unsubscribes when you need to connect a message to a subscriber action read-only system data views in SFMC. They are also the layer that supports campaign-level summaries and per-subscriber analysis, which is why ecommerce teams lean on them for retention audiences, suppression logic, and lifecycle measurement 24 Data Views and their reporting role.
What to do first
Start by deciding whether the question is about a send, an engagement event, or a lifecycle status. That one choice determines which table to query and whether you need to archive the result into a custom Data Extension before the platform drops the row. If the answer has to survive beyond the native retention window, the query is only half the job.
Practical rule: use Data Views for telemetry, then persist the result somewhere you control if the insight has to live longer than a campaign cycle.
That split is the effective fix. You query the system table for what happened, then copy the result into your own reporting layer so cart recovery, win-back, and suppression logic don't disappear with the platform's retention clock.
What SFMC Data Views Are
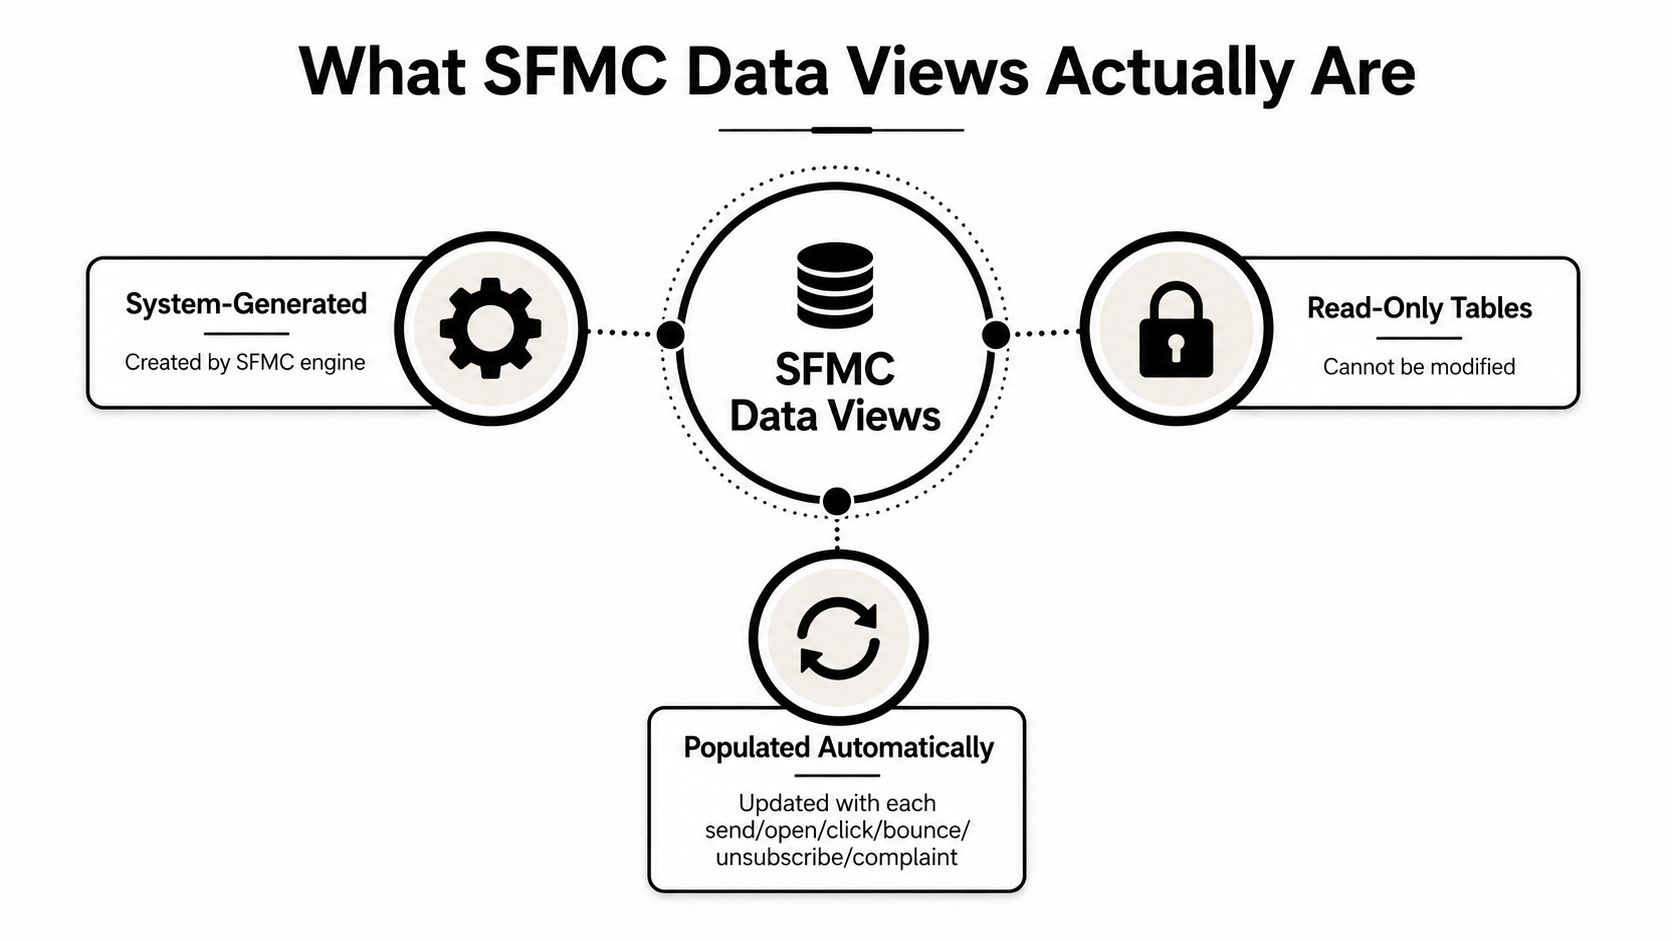
SFMC Data Views are system-generated, read-only tables. They populate automatically as sends, opens, clicks, bounces, unsubscribes, and complaints happen, and they cannot be edited in the UI. That structure separates transactional event capture from analytical storage, which is useful in practice, but it also means the platform does not keep history for you.
How to Query Them
The usual path is SQL Query Activity in Automation Studio, not the Email Studio or Journey Builder UI. You can join Data Views to each other or to Data Extensions, and you can also reference them from AMPscript with Lookup functions when you need message-time logic.
The retention limit is the part teams miss. Standard engagement views such as _Sent, _Open, _Click, _Bounce, _Unsubscribe, _Complaint, and _Job keep only about 6 months of data, so older rows stop being queryable through SQL. Treat that as a hard platform constraint, not a suggestion.
Practical rule: if you need annual history, archive the result before you need the report.
That is the difference between a usable analytics layer and a dead end. Data Views are good for active telemetry, but they are not your warehouse.
How the Views Are Organized by Purpose
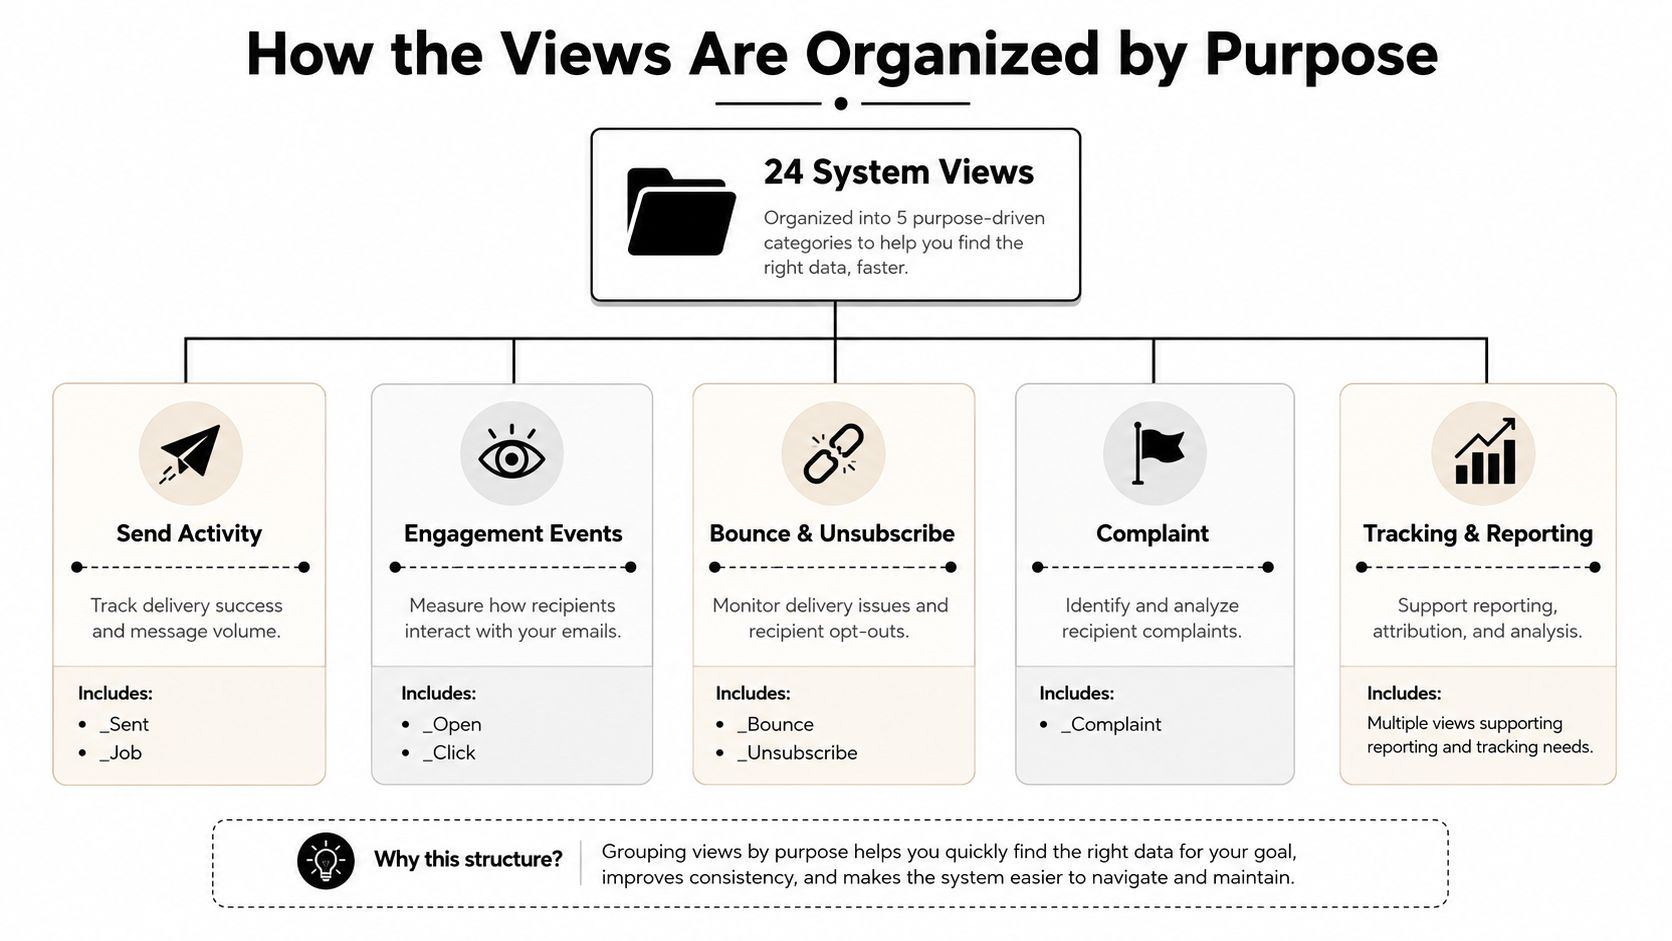
The fastest way to use the 24 Data Views is to sort them by the business question you need to answer, not by the table name. For ecommerce teams, that usually means separating send activity, engagement events, deliverability signals, subscriber status, and journey or automation telemetry. Once the views are grouped that way, the joins become much easier to reason through. A diagram illustrating the five organized categories of 24 Salesforce Marketing Cloud system data views.
The fields that make joins predictable
Most of the commonly used views share a core set of fields, including SubscriberKey, EventDate, JobID, and, in triggered contexts, TriggeredSendID. That overlap is what lets analysts move from message activity to subscriber history without building a separate model for every campaign. In practice, the join path usually becomes obvious once you know whether the event is keyed at the job level or the subscriber level.
The table name matters less than the decision you are trying to support. If you need to know whether a send went out, start with send activity. If you need to know whether anyone reacted, move to engagement. If you need to know whether a contact is becoming risky to email, use the deliverability tables. If you need to know what happened inside a path, use journey telemetry.
- Open rate question: start with _Open and join back to _Sent.
- Deliverability question: start with _Bounce and review subscriber status.
- Repurchase or lifecycle question: start with _Subscribers, then join commerce data.
- Journey exit question: start with _Journey and _JourneyActivity.
That map keeps ecommerce analysis grounded in the right table from the start. It also avoids the common mistake of querying the wrong view, then trying to force the result into a cart recovery, win-back, or suppression decision after the fact.
Subscriber and Send Activity Views Explained
_Subscribers is the status table you use when you care about the contact, not the individual message. It contains fields such as SubscriberKey, EmailAddress, Status, DateCreated, DateUnsubscribed, and the bounce and held counts, which makes it the right place to check whether a person is still eligible for sends. If a repurchase audience looks smaller than expected, this is usually where you find the answer.
_Subscribers and _Sent in practice
A basic subscriber-status count can be built straight from the table.
SELECT Status, COUNT(*) AS SubscriberCount FROM _Subscribers GROUP BY Status
That count helps you separate active, held, unsubscribed, and bounced contacts without guessing at lifecycle status. For ecommerce teams, it's the cleanest way to audit who can still receive a browse or cart recovery flow.
_Sent tells you who was sent to, not who engaged. Its common fields include SubscriberKey, EventDate, JobID, ListID, BatchID, TriggeredSendID, and IsUnique, and that makes it useful for recipient volume, not behavioral interpretation. A subscriber can appear in _Sent and still never open the email.
SELECT JobID, COUNT(*) AS TotalRecipients FROM _Sent WHERE EventDate >= DATEADD(day, -30, GETDATE()) GROUP BY JobID
Use _Sent when you need per-recipient send volume or when you're reconciling a campaign against an export. Don't use it as a stand-in for engagement. That's how teams end up treating delivery as conversion.
_Job for the campaign summary
_Job sits at the campaign level. Its core fields include JobID, EmailName, EmailSubject, ScheduledTime, SendType, and DeliveredTime, which makes it the better choice for send metadata and campaign-level summaries. If the question is “what did we send and when,” this is the table to start with.
Practical rule: use _Sent for recipient-level volume, _Job for the message-level summary, and _Subscribers for lifecycle status.
That separation matters because each table answers a different business question. If you collapse them too early, you lose the distinction between delivery, eligibility, and campaign setup.
Engagement Event Views in Practice
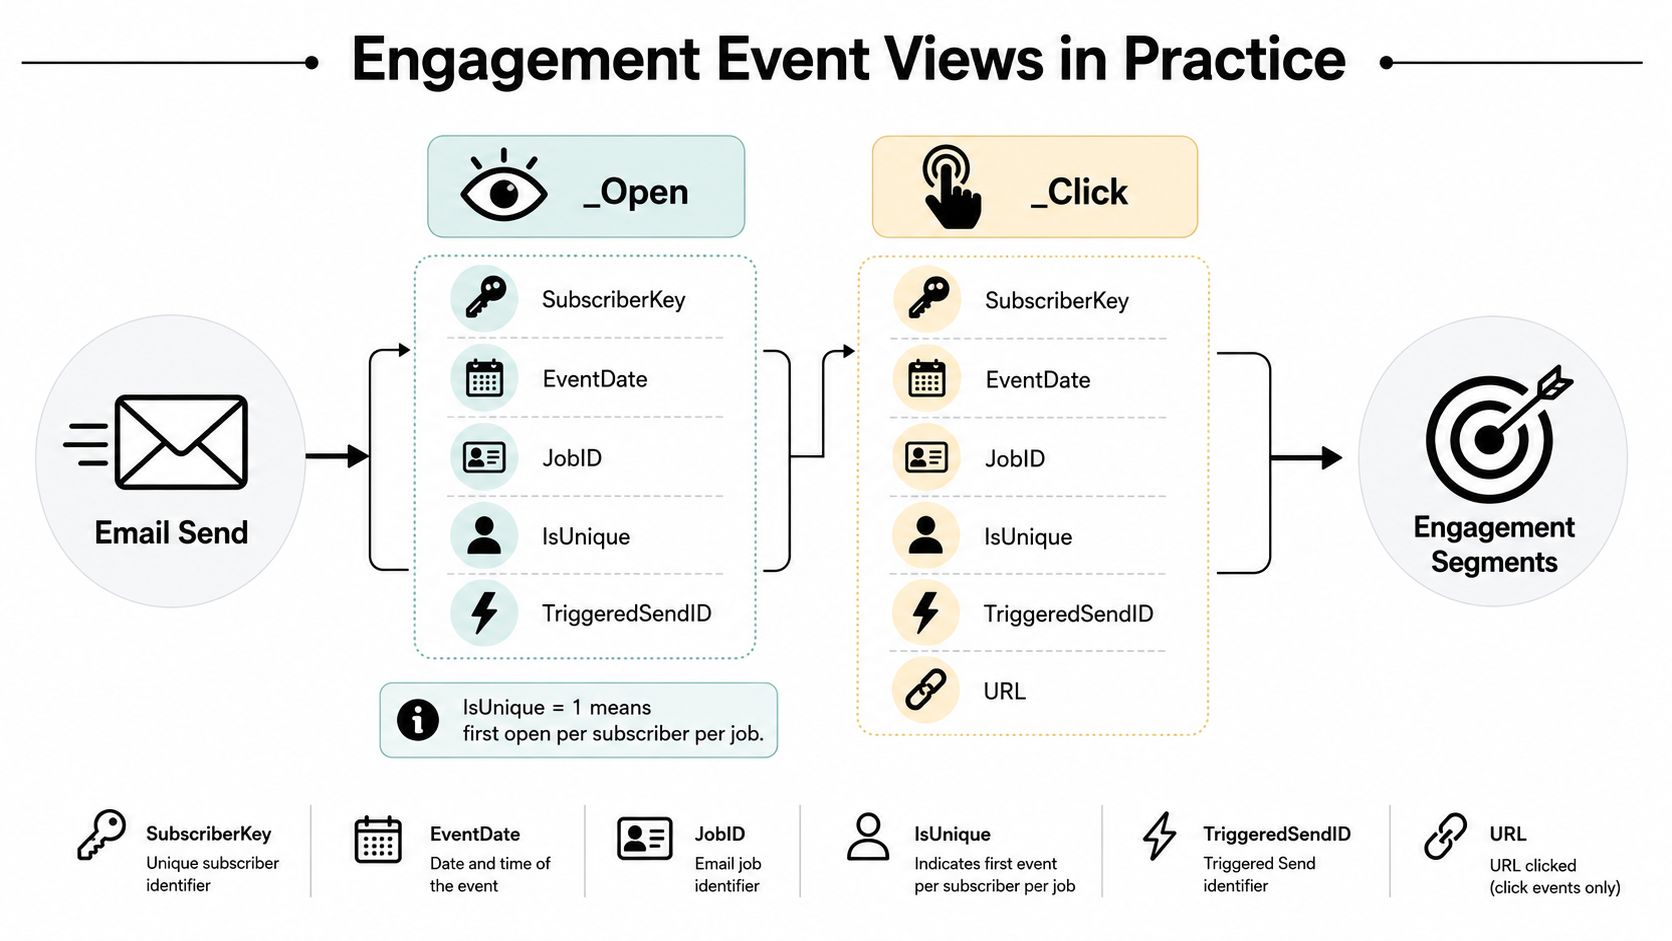
_Open and _Click drive most engagement segments, but they don't mean the same thing. _Open records email opens and includes fields like SubscriberKey, EventDate, JobID, IsUnique, TriggeredSendID. The field that trips teams up is IsUnique, because it marks the first open per subscriber per job, which is the difference between a clean unique-open report and a double-counted mess.
Reading open and click data correctly
A useful unique-open query starts with the job and the event date, then filters to unique opens.
SELECT JobID, COUNT(*) AS UniqueOpens FROM _Open WHERE IsUnique = 1 AND EventDate >= DATEADD(day, -90, GETDATE()) GROUP BY JobID
_Click adds more depth because it exposes fields such as URL, LinkName, and LinkContent alongside the standard event fields. That means you can evaluate per-link performance inside the native tables instead of exporting every click stream first. For ecommerce teams, that's useful when the message contains multiple product links and you want to know which link pulled the buyer forward.
A simple click-to-open ratio by subscriber can be built by joining click activity back to send activity.
SELECT c.SubscriberKey, COUNT(*) AS Clicks FROM _Click c INNER JOIN _Sent s ON c.JobID = s.JobID AND c.SubscriberKey = s.SubscriberKey GROUP BY c.SubscriberKey
If you need the full engagement path for an automation or Journey Builder flow, the same tables still work. The link between send and click is what turns raw activity into a usable segmentation rule.
If your setup depends on automated paths, the mechanics line up with the guidance in email automation workflows.
Deliverability and Journey Views Explained
A bounce, unsubscribe, or complaint record is usually the first place to look when a send starts losing reach. _Bounce, _Unsubscribe, and _Complaint hold the operational detail that matters at the table level, and _Bounce is the most useful starting point because it commonly exposes SubscriberKey, EventDate, BounceCategoryID, BounceSubcategoryID, and SMTPCode. That structure lets you separate hard delivery failures from softer ones without guessing, which is the practical starting point for understanding what email deliverability is.
Bounce subcategory codes 1 and 2 usually point to block bounces, while 3 through 10 usually point to soft bounces. That split matters because recurring bounce behavior affects subscriber status, and a row-by-row query is the only clean way to see whether a contact is drifting toward suppression or still worth keeping active bounce and retention details in SFMC views.
A practical sunsetting rule starts with recent hard-bounce activity, then adds complaints before you suppress the contact from future sends.
SELECT SubscriberKey FROM _Bounce WHERE EventDate >= DATEADD(day, -30, GETDATE()) AND BounceSubcategoryID IN (1,2)
Pair that result with complaint history, then move the combined audience into a suppression Data Extension. The point is not to over-engineer the query, it is to keep obviously damaged records out of circulation before they keep dragging deliverability down.
If a lifecycle path keeps leaking at different stages, fix revenue leaks with mapping gives the right frame for tracing where the drop-offs happen. The deliverability side still needs a clear read on the mailbox behavior itself, so the audit should stay grounded in bounce, complaint, and unsubscribe records instead of broad assumptions.
Journey telemetry without guesswork
Journey reporting gets useful once you tie the flow back to JourneyID, JourneyName, VersionID, ActivityID, ActivityName, and EventDate. _Journey and _JourneyActivity provide the context that shows where contacts move, where they stall, and which step carries the path. For a win-back flow, a short exit report is often enough to show whether the journey is still behaving the way the team designed it.
SELECT JourneyName, ActivityName, EventDate FROM _JourneyActivity WHERE JourneyName = 'Win-Back'
That level of output is usually enough for journey-level reporting and operational checks. Anything more complex belongs in an archived reporting layer, especially once the six-month retention window starts cutting off the history you wish you had kept.
Ecommerce SQL Recipes With Data Views
Browse and cart recovery starts with behavior, not assumptions. Join _Subscribers to _Open and _Click on SubscriberKey, filter for activity in the last 14 days, and exclude anyone who already has a purchase in your synced order Data Extension. Then write the result to a cart-recovery engaged audience so Journey Builder can pick it up cleanly. That keeps recovery targeting focused on people who interacted.
Three templates that work in daily operations
For engagement segmentation, classify the last 90 days into opens-only, clicks, and dormant by combining _Sent, _Open, and _Click. The practical use is simple, those buckets can feed entry conditions for a nurture flow, a reactivation path, or a lighter-touch promotional cadence. The query logic stays manageable as long as you keep the event window consistent.
For lap-of-buyer detection, pull _Sent and the latest click date per subscriber, then flag customers with no engagement for 90-plus days. That audience is the right starting point for a win-back flow, especially when you want to avoid sending the same offer to active buyers and dormant buyers alike. If you want a broader analytics lens around this kind of lifecycle work, analytics for email marketing is a useful companion.
Practical rule: archive the result of each recipe into a dedicated Data Extension, then let the journey consume that DE instead of querying the system view repeatedly.
That pattern keeps the logic reusable. It also makes the audience visible outside the query editor, which helps when marketing and operations need to inspect the output before a send.
What Data Views Don't Cover
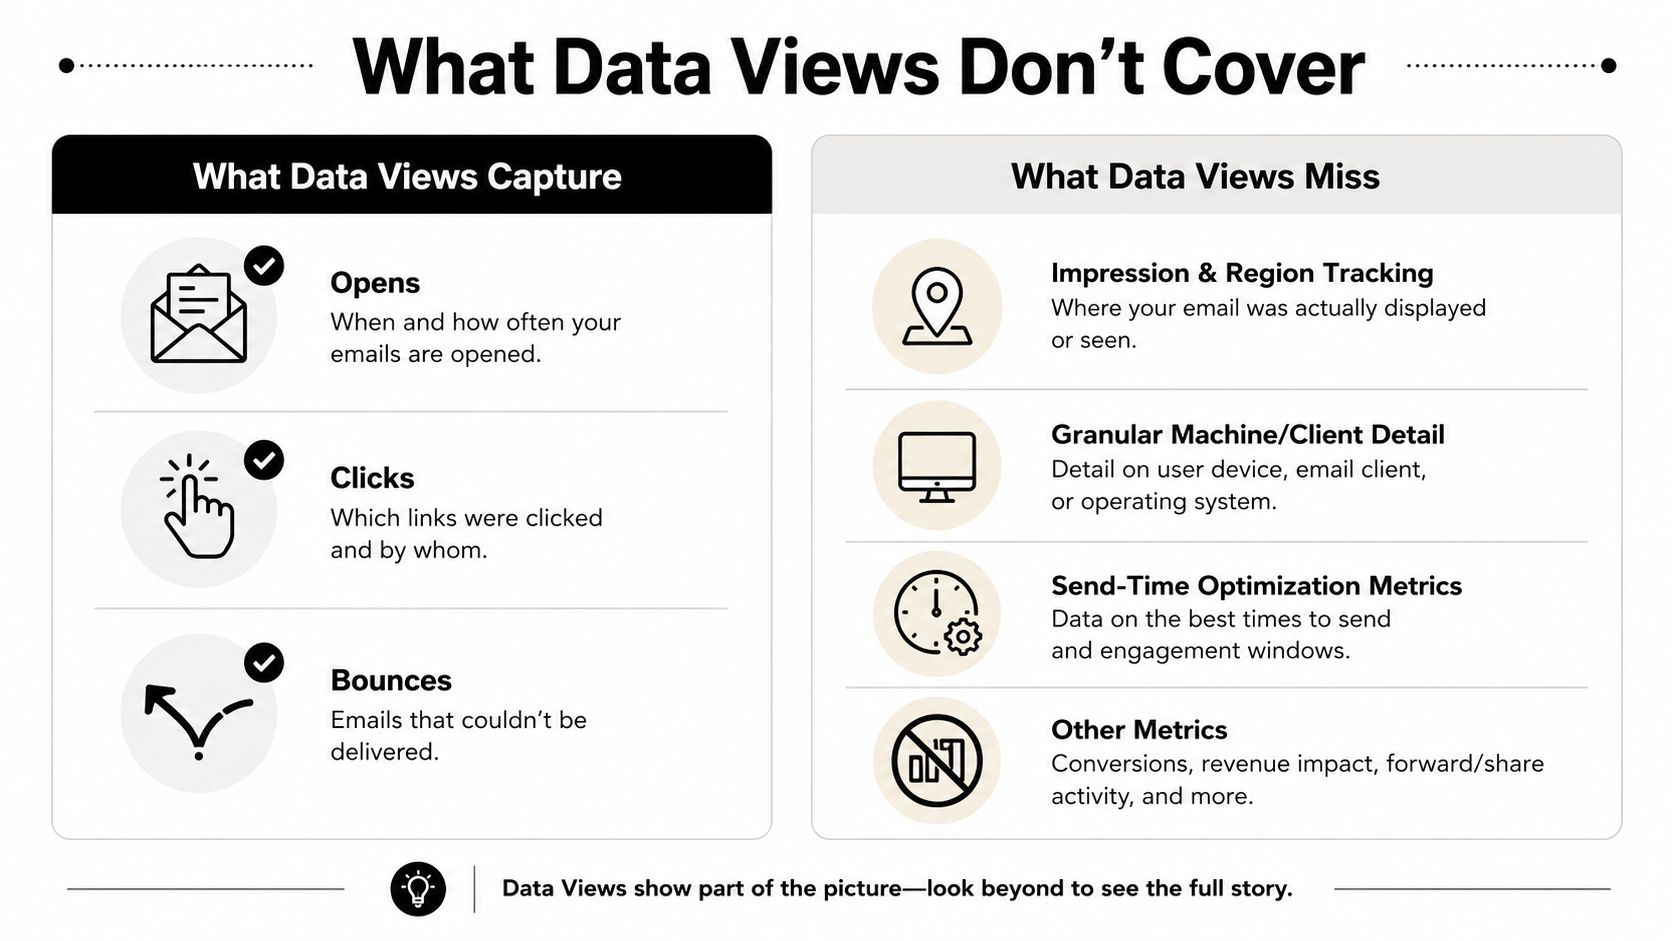
Data Views are strong on engagement, weak on everything they were never designed to store. They capture opens, clicks, bounces, unsubscribes, complaints, and send metadata, but they do not expose impression-region tracking as a Data View, and they don't replace the need for extracts when you need that kind of reporting missing impression-region tracking in Data Views. They also don't give you the kind of granular machine or client detail that would let you build device-level attribution from the native tables alone.
Use the right layer for the right question
Treat Data Views as the engagement layer, not the warehouse. If you need revenue, product, or order truth, pair them with a synced order or product Data Extension. If you need campaign attribution that stretches across a longer horizon, copy the event rows out first and do the heavier analysis elsewhere.
That boundary keeps reporting honest. It also prevents teams from overpromising what the native tables can answer.
Retention Limits and Archiving Patterns
A retention problem usually shows up too late. The native engagement views can look reliable in day-to-day reporting, then the history disappears once you try to answer a longer-cycle question. Standard engagement views like _Sent, _Open, _Click, _Bounce, _Unsubscribe, _Complaint, and _Job only keep about 6 months of queryable history, so older rows are no longer available for the kind of annual trend work or lifecycle analysis that ecommerce teams eventually need.
A practical archive pattern
The safest pattern is to copy event rows out while they are still available. Run a daily or weekly Automation Studio SQL Query Activity that pulls the prior day's rows from each view with a filter such as WHERE EventDate >= DATEADD(day, -1, GETDATE()), then write those rows into a dedicated retention Data Extension keyed on SubscriberKey and EventDate. If your downstream warehouse is the long-term system of record, mirror the archive there as well. If the retention Data Extension needs cleanup for your reporting process, remove duplicate records after the warehouse copy is complete. The point is straightforward, preserve the event before the platform drops it.
That pattern gives ecommerce teams a longer measurement window without pretending the native tables keep everything forever. It also keeps the archive incremental, which is easier to maintain than trying to recover missing history after the cutoff has already passed.
Common Errors and Fixes When Querying Data Views
The first common error is an empty result set. A date filter against EventDate usually works, but when you join to a synced Data Extension, mismatched field types can break the comparison. The fix is to use CONVERT or CAST so the types line up before the filter runs.
The second is a slow or timed-out query. That usually happens when someone pulls _Open or _Click across all history with SELECT * and no date filter. Tighten the window to something like 90 days and select only the fields you need.
The third is duplicate rows after joining _Sent to _Open. That almost always happens when the join uses SubscriberKey alone instead of SubscriberKey plus JobID, and sometimes IsUnique if the metric needs it. The join key has to match the event grain or the math falls apart.
- Validate the Object ID in the query.
- Run the query from a test automation.
- Check the DE primary key before writing results.
- Verify the date column type on every joined table.
- Compare row counts before and after the
WHEREclause.
That checklist catches most bad queries before a support ticket ever gets opened.
Quick Reference for Every Data View
| View | Purpose | Key Fields | Retention | Ecommerce Use Case |
|---|---|---|---|---|
| _Subscribers | Contact status and lifecycle eligibility | SubscriberKey, EmailAddress, Status, DateCreated, DateUnsubscribed, bounce counts | About 6 months for native visibility | Build suppression, reactivation, and repurchase audiences |
| _Sent | Recipient-level send activity | SubscriberKey, EventDate, JobID, ListID, BatchID, TriggeredSendID | About 6 months | Reconcile sends for cart recovery or broadcast campaigns |
| _Open | Email open events | SubscriberKey, EventDate, JobID, IsUnique, TriggeredSendID | About 6 months | Measure engagement for win-back and nurture flows |
| _Click | Click engagement and link detail | SubscriberKey, EventDate, JobID, URL, LinkName, LinkContent | About 6 months | Track product-link performance and interested buyers |
| _Bounce | Bounce and deliverability signals | SubscriberKey, EventDate, BounceCategoryID, BounceSubcategoryID, SMTPCode | About 6 months | Suppress risky contacts and monitor list quality |
| _Unsubscribe | Opt-out events | SubscriberKey, EventDate, JobID, ListID, BatchID | About 6 months | Protect list health and segment opt-out trends |
| _Complaint | Spam complaint events | SubscriberKey, EventDate, JobID, IsUnique | About 6 months | Identify sender risk before it spreads |
| _Job | Campaign metadata and send summary | JobID, EmailName, EmailSubject, ScheduledTime, SendType | About 6 months | Attribute campaign-level sends and timing |
| _Journey | Journey-level metadata | JourneyID, JourneyName, VersionID, EventDate | Varies by journey context | Review journey structure and version reporting |
| _JourneyActivity | Activity-level journey events | JourneyID, ActivityID, ActivityName, EventDate, VersionID | Varies by journey context | Attribute exits and step-level performance |
FAQ on SFMC Data Views
Can I join a Data View to a synced Data Extension? Yes, as long as the join key types match, usually SubscriberKey. Type mismatches are one of the fastest ways to get empty results.
Can AMPscript read a Data View directly? Yes, through Lookup against the view name, although SQL remains the standard approach for reporting and archival work.
What's the difference between _Open and a Journey open tracking event? _Open is the platform-wide event table, while journey-level opens live inside the journey context and aren't stored as separate rows in the same way.
How do I handle queries that need more than 6 months of history? You can't pull data older than the native retention window. Archive the rows into a custom Data Extension before they age out, then query that archive instead.
Ecommerce teams usually don't need more dashboards; they need cleaner event logic and a retention pattern they can trust. If you want help turning SFMC Data Views into cart recovery, win-back, and deliverability reporting that holds up in production, visit Ecommerce Boost and see how the team builds lifecycle systems that connect data to revenue.


