
You've probably seen this in a Shopify export: two customers sit next to each other with the same lifetime revenue, yet one has already consumed its margin through discounts and acquisition cost while the other is becoming the account your retention budget should protect. A revenue-sorted customer list makes them look identical. Their purchase timing, return behavior, margin, subscription status, and probability of buying again tell a different story.
That's the practical job of customer lifetime value modeling. It isn't a dashboard exercise or a more polished version of historical revenue reporting. A useful model changes who receives a discount, who enters a replenishment flow, which customers seed a paid audience, and how much you're willing to pay to acquire the next shopper.
Why Most Ecommerce Brands Misread Their Best Customers
Consider two Shopify customers, both showing $480 in lifetime revenue.
Customer A bought once during a heavily discounted campaign. The order was expensive to acquire, the customer returned part of it, and there's no meaningful engagement afterward. Customer B bought through a subscription offer, renews automatically at six-month intervals, and has a purchase pattern that suggests the relationship could pass $1,400 by year two. That future value is part of the scenario, not a reported result, but the operational difference is obvious.
A revenue-only sort gives both customers the same rank. A retention team that treats the list as truth might send Customer A another broad discount while failing to protect Customer B from cancellation, poor replenishment timing, or an irrelevant promotion.
Practical rule: Historical revenue tells you what a customer has already contributed. Predictive CLV helps decide what that customer is likely to be worth next.
The Shopify blind spots that distort value
The first problem is gross revenue bias. Teams often rank customers by order totals without subtracting refunds, returns, payment adjustments, or the cost of repeated discounting. That makes a high-return shopper appear more valuable than a lower-revenue customer with reliable net margin.
The second problem is identity. Subscription renewals can be counted as separate customer relationships when the underlying account is one continuing customer. Guest checkout emails, alternate addresses, and logged-in profiles can split one person into several records. A later renewal then looks like a new acquisition rather than evidence of retention.
The third problem is lifecycle context. A lapsed VIP and a new subscriber may both have one recent order, but they need different treatment. The VIP has known purchase history and may respond to a carefully timed reactivation message. The subscriber needs education, product confidence, and a frictionless path to the next scheduled order.
A basic RFM customer segmentation framework can expose recency, frequency, and monetary differences, but RFM alone won't forecast future value or account for margin and defection risk.
CLV is a decision system, not a ranking
The useful question isn't “Who spent the most?” It's “Which customer should receive which investment this week?” That requires a customer-level score, a defined forecast window, and a direct connection to email, SMS, paid media, and customer service actions.
The rest of the work is operational: select a model that matches your data, repair the customer table before training, validate against future revenue, and push percentile scores into the systems that can change behavior.
Choosing the Right CLV Modeling Approach for Your Store
A store with irregular repeat purchases needs a different CLV model from a subscription business. The right choice depends on trading history, purchase frequency, subscription revenue, return data, customer identity quality, and how clearly marketers must explain each score.
Microsoft's Dynamics 365 guidance says baseline CLV prediction needs at least one year of transaction history, preferably two to three years, with ideally two to three transactions per customer ID across multiple dates. Its baseline formula multiplies average monthly purchase in the active customer window by the number of months in the prediction period and the overall retention rate. That structure makes recurring transactions, retention, and a defined forecast window central to the model. (Microsoft's CLV guidance summarized for ecommerce)
Teams should align definitions before comparing methods. This overview of lifetime value for ecommerce stores provides a useful reference for revenue, margin, retention, and forecast terminology.
| Approach | Min. data history | Handles subscriptions | Cold-start friendly | Best fit |
|---|---|---|---|---|
| Historical CLV | A clean order table, even with limited history | Poorly unless renewal logic is added | Relatively friendly for reporting | Early-stage stores needing a baseline |
| Cohort revenue curves | Enough completed cohorts to observe repeat behavior | Well when cohorts are subscription-aware | Moderate, provided similar cohorts exist | Channel, product, and launch comparisons |
| Pareto/NBD | Meaningful repeat-purchase history | Requires adaptation for contract-like renewal behavior | Weak for customers with little activity | Noncontractual repeat-purchase businesses |
| BG/NBD plus Gamma-Gamma | Repeat dates and monetary history | Useful with careful treatment of renewals | Weak for new customers | Mature stores with repeat orders and interpretable scoring |
| Machine learning, including XGBoost or neural networks | Larger feature set and reliable labels | Strong if subscription, refund, and engagement features are engineered correctly | Can be improved with behavioral and product signals, but remains sensitive to sparse data | Mature teams with warehouse and activation infrastructure |
What works at each stage
A 12-month-old DTC store with two repeat orders per customer shouldn't be running BG/NBD yet. Too little behavioral variation can produce scores that look precise while remaining unstable. Start with net historical CLV, cohort curves, and transparent rules that identify repeat purchase patterns.
A four-year-old brand with 80,000 customers can justify BG/NBD or machine learning, provided customer IDs are trustworthy. Pareto/NBD estimates repeat-purchase probability. BG/NBD combined with Gamma-Gamma separates purchase frequency from expected monetary value. Those outputs become more useful than one store-wide average when the database contains enough observed buying behavior.
Machine learning models such as XGBoost can use refunds, product category, discount dependence, channel, email engagement, and time since last purchase. They can outperform classical approaches, but they require stronger data governance and closer monitoring. A refund-heavy category, duplicated guest profiles, or an acquisition channel that changes rapidly can distort the labels.
The model also has to survive the paid media feedback loop. If high-CLV customers receive more prospecting spend, future value can reflect both customer quality and prior media allocation. Keep acquisition source and campaign features visible, then validate whether the score predicts future net revenue rather than merely reproducing past targeting.
A 2025 fashion ecommerce study trained models on 4.2 million transactions and reported 89% precision for gradient boosting in 12-month CLV forecasts, with 18% lower RMSE than Pareto/NBD baselines. An independent paper summarized AI-driven CLV accuracy at 85-90%, compared with 65-75% for conventional statistical approaches. These figures come from the cited research context, not a guarantee for your store. (2025 CLV research paper)
Choose by data maturity and operational need, not model prestige. A percentile-based score should determine whether a shopper enters a retention, replenishment, VIP, or win-back flow next week. If marketers cannot reconcile the score with orders or use it in email, SMS, paid media, or service decisions, a simpler model is usually better.
Teams moving from forecasting to intervention can review predictive analytics for customer retention for additional retention applications.
Building the Customer-Level Data Foundation
A model trained on broken customer identity is still broken. Before selecting an algorithm, create one canonical customer table that represents net commercial value and preserves the events that explain future behavior.
Start with the source tables
Your warehouse should contain at least these connected datasets:
- Orders: order ID, customer ID, checkout email, order date, currency, subtotal, discounts, shipping, tax, payment status, cancellation status, and acquisition metadata.
- Order items: SKU, quantity, unit price, product category, subscription identifier, and cost where available.
- Refunds: refund ID, original order ID, refund date, refunded amount, currency, and item-level allocation.
- Customer profiles: platform customer ID, normalized email, phone, consent state, first order date, and account creation date.
- Engagement events: email delivery, click, purchase attribution, SMS delivery, click, unsubscribe, and flow membership.
- Paid media touchpoints: platform, campaign, ad set, creative, click identifiers, impression timestamps, and the attribution method used.
Use a documented identity hierarchy. A verified platform customer ID should take priority, followed by normalized email and then carefully reviewed phone or address matches. A guest checkout email should connect to a later logged-in profile only when the match is reliable. Don't merge records merely because names or shipping addresses resemble each other.
Net the money before calculating value
Refunds must join back to the original order, not appear as a negative customer transaction on the refund date. That preserves the purchase event while reducing its realized value. Subscription renewals should retain their revenue and timing, but the customer relationship should remain tied to one stable customer identity.
A simplified canonical feature query might look like this:
create table customer_feature as
select
    c.customer_key,
    min(o.order_date) as first_order_date,
    count(distinct o.order_id) as order_count,
    sum(o.gross_revenue - coalesce(r.refund_amount, 0)) as revenue_net,
    sum(coalesce(r.refund_amount, 0)) / nullif(sum(o.gross_revenue), 0) as refund_rate,
    avg(date_diff('day',
        lag(o.order_date) over (
            partition by c.customer_key order by o.order_date
        ),
        o.order_date
    )) as avg_days_between_orders,
    sum(
        case when e.event_type in ('click', 'sms_click')
        then 1 else 0 end
    ) as email_engagement_score,
    max(o.acquisition_channel) as acquisition_channel
from canonical_customer c
left join canonical_orders o
    on c.customer_key = o.customer_key
left join refunds r
    on o.order_id = r.order_id
left join engagement_events e
    on c.customer_key = e.customer_key
group by c.customer_key;
This is illustrative SQL, not a drop-in Shopify schema. Window functions, refund allocation, and currency conversion need to match your warehouse.
Audit the failure points
Cancelled orders, partial refunds, discount-code attribution conflicts, and multi-currency orders can all corrupt naive joins. Decide whether revenue is reported in transaction currency or a normalized reporting currency, and record the conversion rate used.
Your customer table should also preserve acquisition channel versions. A first-touch channel, last-touch channel, and blended attribution channel answer different questions. Store them separately rather than forcing one disputed value into the CLV feature set.
Treat this work as part of a first-party data strategy. Clean identity and consent-aware behavioral history make the model more useful than another layer of dashboard logic.
Training and Validating Your CLV Model in Python
For a repeat-purchase store with enough history, BG/NBD and Gamma-Gamma provide an interpretable starting point. BG/NBD estimates how often a customer is likely to purchase and whether the customer is still active. Gamma-Gamma estimates future monetary value from observed spend. A gradient-boosted regressor can then add a fixed-horizon forecast, such as 90-day CLV, using engineered behavioral and commercial features.
Build the training frame
Define an observation cutoff first. Only use data available on or before that date for features. Label each customer with realized net revenue after the cutoff during the forecast window. This prevents future purchases, refunds, or post-purchase engagement from leaking into the training data.
from lifetimes import BetaGeoFitter, GammaGammaFitter

# summary contains frequency, recency, T, and monetary_value
bgf = BetaGeoFitter(penalizer_coef=0.01)
bgf.fit(
    summary["frequency"],
    summary["recency"],
    summary["T"]
)

ggf = GammaGammaFitter(penalizer_coef=0.01)
ggf.fit(
    summary["frequency"],
    summary["monetary_value"]
)

summary["predicted_purchases"] = bgf.conditional_expected_number_of_purchases_up_to_time(
    90,
    summary["frequency"],
    summary["recency"],
    summary["T"]
)

summary["predicted_value"] = ggf.customer_lifetime_value(
    bgf,
    summary["frequency"],
    summary["recency"],
    summary["T"],
    summary["monetary_value"],
    time=3,
    freq="M"
)
The parameterization must match your order frequency and currency conventions. Exclude customers who violate the model assumptions, such as accounts created through a subscription system whose renewals aren't represented as comparable purchase events.
Respect time and cohort drift
Use time-based train and validation splits, not random rows. A random split can let the model learn holiday patterns, product availability, or promotion behavior that won't exist when the score is used.
A practical validation design trains on an earlier observation window, validates on a later window, and then repeats the exercise across another cutoff. Compare predicted value with realized net revenue at 30, 60, and 90 days. Track the result by acquisition channel, signup cohort, subscription status, product category, and refund behavior.
For a boosted model, engineered features can include order count, days since last order, average days between orders, net AOV, refund rate, discount share, subscription flag, product mix, email clicks, SMS clicks, and acquisition channel. Don't include events that occur after the scoring date.
Measure decisions, not just error
A model can have acceptable aggregate error while ranking the wrong customers. Marketing needs to know whether the highest-scored customers generate more future revenue than the rest.
| Metric | What It Measures | Why It Matters for Ecommerce |
|---|---|---|
| Holdout MAE | Average absolute gap between predicted and realized value | Keeps forecast error in currency terms that finance can interpret |
| MAPE by decile | Relative error within each predicted-value group | Reveals whether the model fails for VIPs or low-value shoppers |
| Decile gain | Realized revenue from a scored group compared with the overall baseline | Shows whether segmentation can concentrate investment |
| Top-10% capture | Share of future value found in the highest-scored group | Tests whether VIP targeting is finding future value, not past revenue |
| Calibration curve | Predicted value compared with realized value across score ranges | Shows whether bids and incentives are based on inflated scores |
import numpy as np

def mape_by_decile(df, actual_col, prediction_col):
    data = df.copy()
    data["decile"] = pd.qcut(
        data[prediction_col],
        10,
        labels=False,
        duplicates="drop"
    ) + 1
    data["abs_pct_error"] = (
        (data[actual_col] - data[prediction_col]).abs()
        / data[actual_col].replace(0, np.nan)
    )
    return data.groupby("decile")["abs_pct_error"].mean()
Holiday windows can poison frequency features, while a sudden shift in refund rates can degrade scores. Monitor feature distributions after launch and retrain when the commercial process changes, not only when the calendar says it's time.
Turning CLV Scores Into Lifecycle Marketing Action
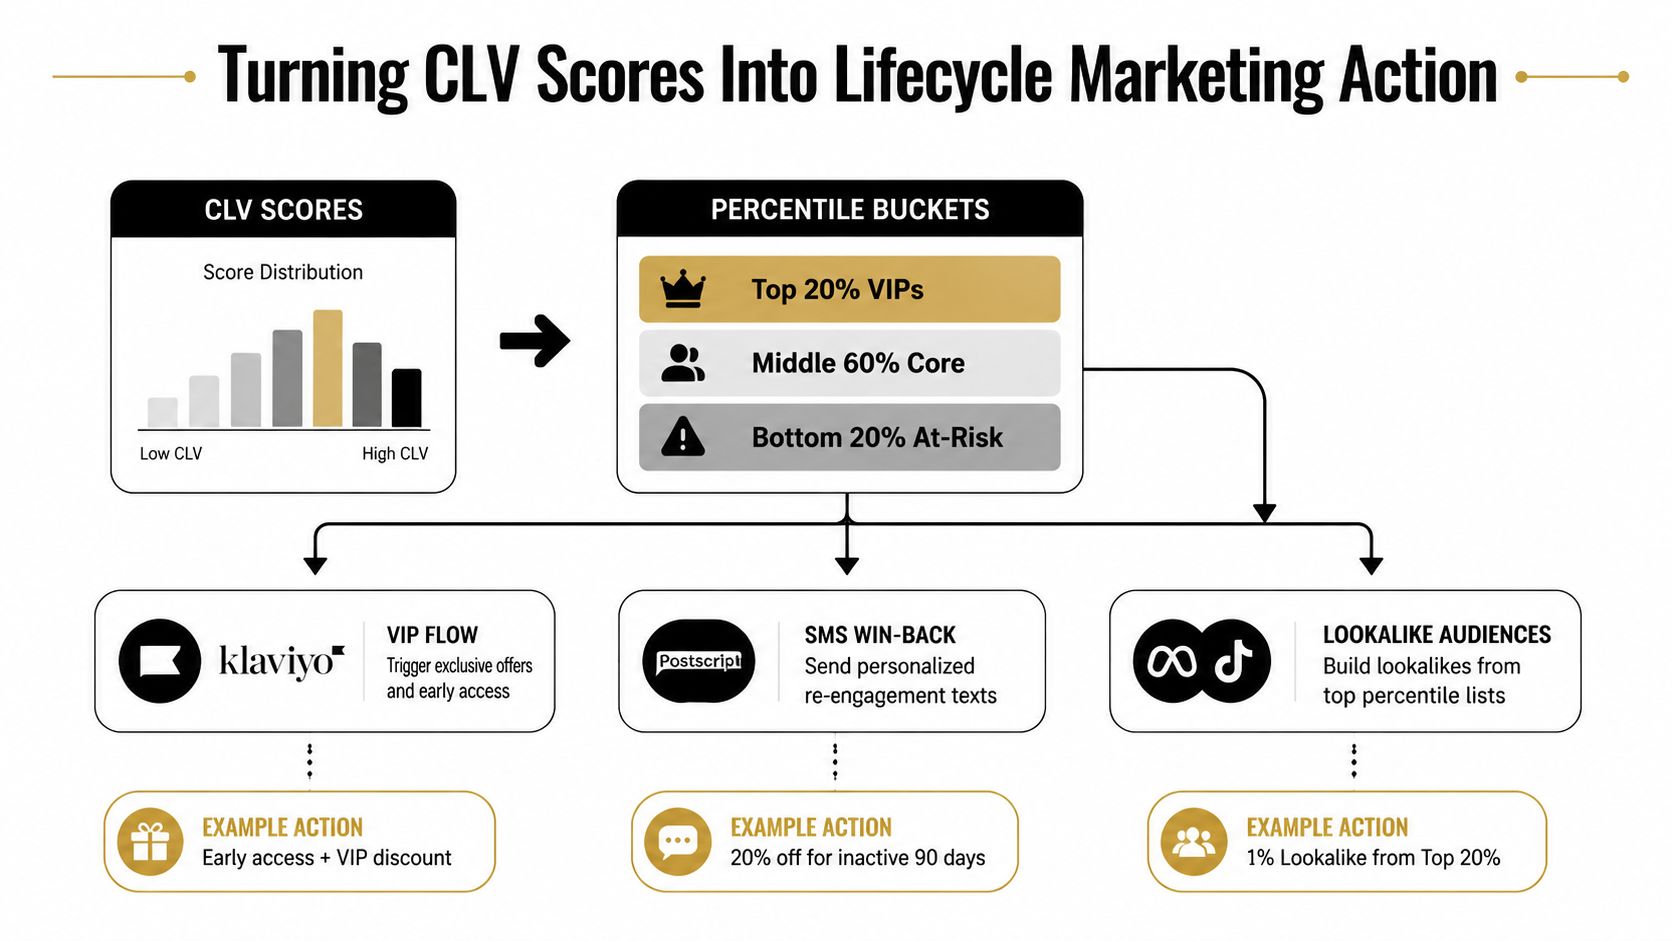
An unactivated CLV model is shelfware. The score earns its keep only when it changes the next email, SMS message, audience sync, or bid.
Replace absolute thresholds with percentile tiers
Absolute CLV cutoffs become stale when pricing, product mix, or acquisition sources change. Percentile buckets adapt to the current customer distribution:
- Top percentile: Protect margin and relationship quality. Use VIP welcome variants, early access, product education, and service recovery instead of default discounts.
- Middle percentile: Improve purchase frequency. Trigger replenishment around predicted purchase dates, recommend compatible products, and test bundles where the margin supports them.
- Lower percentile: Decide whether the customer is at risk or early in the relationship. Use a measured winback path rather than treating every low score as a lost account.
In Klaviyo, sync the score and percentile as customer properties. Add flow entry conditions that check the latest score, consent status, last order, subscription state, and whether the customer has already received an incentive. Postscript can use the same logic for SMS win-back audiences, with frequency controls and suppression for recent purchasers.
A top-tier welcome series should not necessarily look like a standard new-customer sequence. A customer predicted to become valuable may receive education, access, and service reassurance. A discount-driven shopper may need a product-use sequence that tests whether value can be created without another promotion.
Let the forecast control the intervention
A replenishment flow should use predicted purchase timing where the category supports it. If the predicted date passes, increase the relevance of the message before increasing the discount. A winback flow should be gated by forecasted value, not recency alone. A recently inactive customer with strong expected value deserves more attention than a highly recent customer whose behavior produces little net margin.
Margin-aware CLV matters here. Subtract product cost, refunds, shipping support, and discount exposure where the data allows. Discount hunters shouldn't automatically become VIPs because their gross order totals are high.
Paid media needs the same feedback loop. Export high-percentile customer lists to Meta, TikTok, and Google, then compare acquisition quality by predicted and realized value rather than first-order revenue. Use the scores to guide bidding and audience construction, but retain holdouts or controlled tests so the ad platform doesn't optimize toward customers you would have acquired anyway.
For practical retention ideas beyond the mechanics, how to boost CLV is a useful complementary resource. The operating principle remains simple: a score should change treatment, not decorate a report.
Going Beyond the Average Customer Lifetime Value
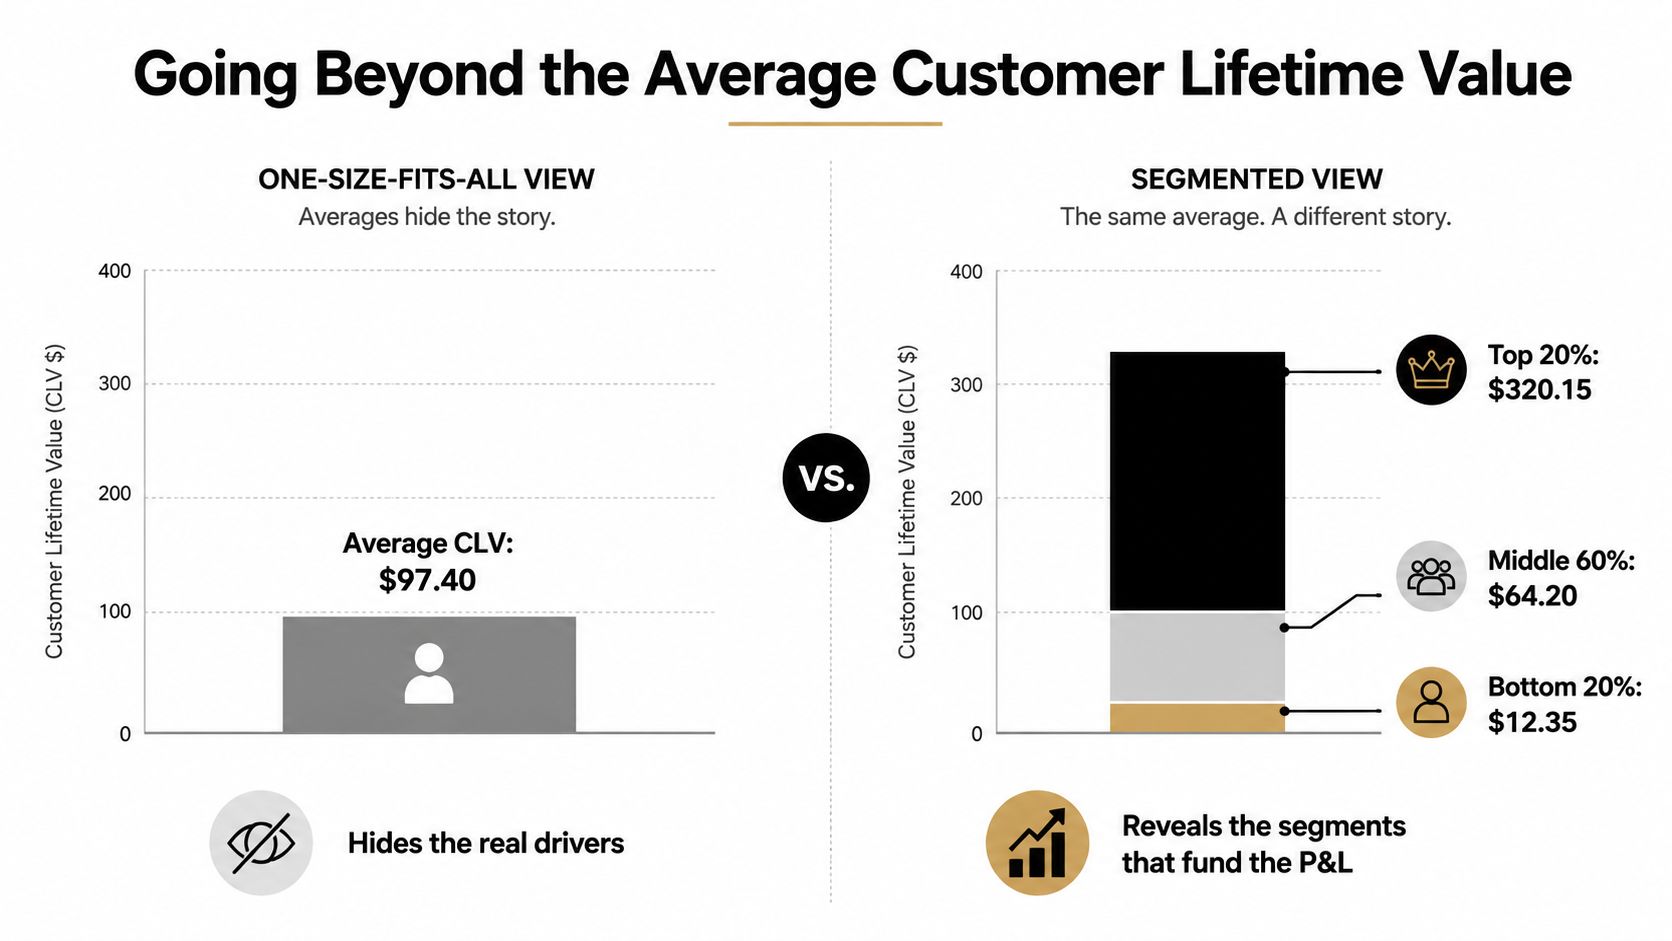
The average CLV number is attractive because it fits neatly into a quarterly review. It's also capable of hiding the customers funding the P&L.
Averages combine one-time buyers, repeat purchasers, subscribers, return-heavy accounts, and dormant customers into one summary. A major modeling gap is the distribution of value by cohort and customer segment, rather than a single best estimate. A 2026 business guide makes the same contrarian case, warning that a mean can hide extreme skew and that static snapshots become stale when customers re-engage through other channels. (2026 CLV modeling guide)
Report the shape of value
Build a CLV distribution chart with percentile bands, not only a blended KPI. Then add cohort curves by acquisition channel, showing how net value accumulates after the first purchase. This reveals whether a channel creates broad, dependable value or a narrow group of exceptional customers surrounded by weak economics.
Add a reactivation-adjusted view. Dormant buyers shouldn't receive full future-value credit merely because they once spent heavily. Credit reactivation only after a winback flow produces profitable net revenue, and track the intervention that preceded the return.
Many retention reviews need a more honest operating table:
| View | Question it answers | Action it supports |
|---|---|---|
| CLV distribution | Which percentile groups create future value? | Tier service, offers, and flow treatment |
| Cohort curve | How does value develop after acquisition? | Shift budget toward durable acquisition sources |
| Reactivation queue | Which dormant customers are worth contacting? | Prioritize profitable winback work |
| Payback by channel | How quickly does net value recover acquisition cost? | Set channel-specific spending limits |
A worked comparison without blended comfort
Suppose two acquisition channels show the same blended CAC. That doesn't make them economically equivalent. Channel A might produce a broad middle of customers who purchase again, while Channel B generates a small top tier with high future value and a large group that never repeats.
Separate the channels by top-percentile CLV and 180-day repurchase probability. The channel with the stronger top tier may deserve a dedicated lookalike audience, while the channel with more dependable middle-tier behavior may justify stronger replenishment investment. The point isn't to declare one channel universally better. It's to stop blended CAC from deciding a retention question it can't answer.
Research has shown why historical profitability is a weak proxy for future CLV. Among the top 20% of customers by past profit, about 55% would be misclassified and miss special treatment, while about 15% of the future bottom 80% would be incorrectly given special treatment. (Study on customer profitability and future value)
That evidence supports a distribution-first operating model. Replace the KPI tile with a value chart, a payback-by-channel table, and a dormant-customer reactivation queue. For a simple starting point, use a customer lifetime value calculator to establish the baseline, then graduate to cohort and percentile reporting.
A visual explanation can help stakeholders see why the average hides more than it reveals.
Your Customer Lifetime Value Modeling Checklist
A CLV project usually stalls in the handoff from analysis to operations. Before committing the next quarter's budget, test the data, model, validation plan, and activation path together. The score should change which email or SMS flow a shopper enters next week, not only update a dashboard tile.
Data readiness
Confirm that the model reflects commercial reality.
- History: Verify at least 12 months of order history before training a baseline predictive model. Use longer history when available, especially for stores with seasonal demand.
- Identity: Join guest-checkout emails to later profiles only through a documented match rule. Review collision cases before training.
- Returns: Link refunds to original orders and calculate customer-level net revenue.
- Spend: Include marketing spend by channel and document the attribution convention used for payback and acquisition comparisons.
- Cutoff: Set a cohort cutoff, then exclude every event after the scoring date from the features. Post-purchase engagement cannot become evidence available at the earlier decision point.
Model selection
Match model complexity to the decision the team needs to make.
Use historical CLV for a dependable backward-looking baseline. Use cohort curves when channel or product changes shape repeat behavior. Use BG/NBD plus Gamma-Gamma when repeat-order history is deep enough to estimate purchase probability and spend. Use gradient boosting when behavioral, margin, refund, subscription, and acquisition fields are trustworthy and consistently populated.
A stronger workflow models purchase timing, purchase amount, and defection risk together. A validated hierarchical Bayes approach did so and outperformed competing models on a separate validation set for CLV prediction and for targeting valuable customers. (Hierarchical Bayes CLV research)
Validation gates
Do not approve a model because its overall error looks acceptable.
- Calibration: Plot predicted against realized net revenue across score ranges.
- Holdout error: Set a revenue threshold for holdout MAE before reviewing results.
- Decile lift: Require monotonic lift across predicted deciles. If rankings break, inspect sparse history, returns, and channel mix.
- Segment stability: Review cohorts, channels, subscription status, product type, and refund behavior separately.
- Forecast windows: Compare realized outcomes at 30, 60, and 90 days when the model supports those horizons.
Operational wiring
Assign ownership before production. Define the scoring cadence, warehouse sync, destination fields, and suppression rules while the model is still being reviewed.
- Platform sync: Send customer scores and percentile tiers to Klaviyo or Iterable.
- Flow logic: Set entry conditions for score tier, consent, recency, subscription state, and recent incentive exposure.
- Paid audiences: Refresh Meta, TikTok, and Google audiences on a schedule that matches campaign planning.
- Refresh ownership: Assign a quarterly owner for model review, feature drift, refund shifts, and threshold changes.
- Revenue feedback: Store the message, offer, and channel that followed each score so the team can evaluate incremental outcomes.
Common failures include training on gross revenue, ignoring returns, scoring frozen customers without a reactivation policy, and treating CLV as one number instead of a distribution. Use percentile tiers to route shoppers into different retention treatments, then compare revenue by tier and treatment. Keep the paid-media feedback loop separate from the retention decision, so acquisition volume does not obscure customer value.
Ecommerce Boost helps online retailers use customer data for email campaigns and automated welcome, browse, cart recovery, post-purchase, and win-back flows, alongside segmentation, testing, creative, and deliverability support. If CLV scores are not reaching Klaviyo or lifecycle programs, visit Ecommerce Boost to discuss a retention system built around the store's data.


